語義差異量表
在 Potato 中配置語義差異量表,用兩極形容詞對測量態度,檔位數可自行設定。
語義差異量表標註方案給標註者呈現一組兩極形容詞量表,用於測量態度、感受或概念的內涵意義。每條量表的兩端是一對相反的形容詞(例如 Good 與 Bad),標註者在這條譜系上選一個位置來表示條目落在哪裡。
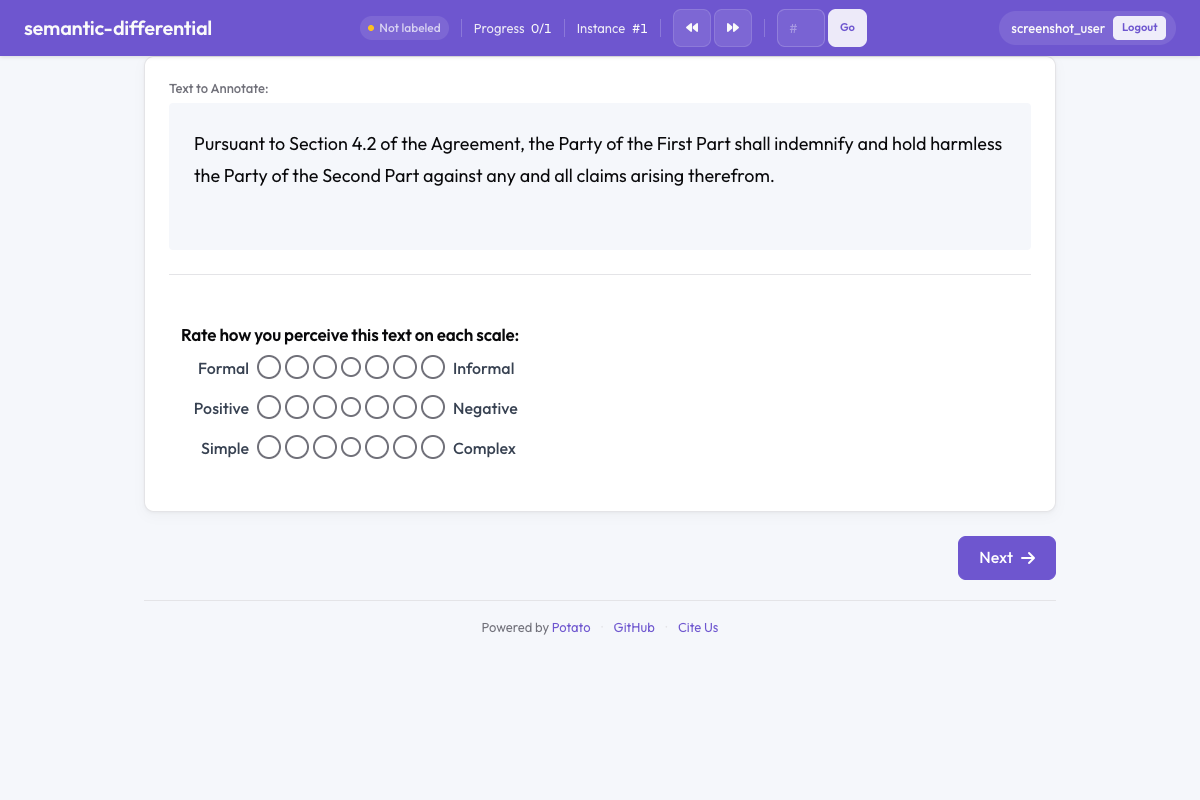 Semantic differential in Potato
概覽
語義差異量表由 Charles Osgood 在 1950 年代提出,是心理學和社會科學中測量概念內涵意義的成熟方法。在標註任務裡,它適合捕捉單一評分量表表達不了的、細緻的多維度感受。
快速開始
yaml
annotation_schemes:
  - annotation_type: semantic_differential
    name: text_perception
    description: Rate how you perceive this text on each scale.
    pairs:
      - ["Formal", "Informal"]
      - ["Positive", "Negative"]
      - ["Simple", "Complex"]
    scale_points: 7
配置項
| 欄位 | 類型 | 預設值 | 說明 |
|---|---|---|---|
annotation_type | string | 必填 | 必須為 "semantic_differential" |
name | string | 必填 | 本方案的唯一識別符號 |
description | string | 必填 | 展示給標註者的說明文字 |
pairs | array | 必填 | [左側形容詞, 右側形容詞] 組成的列表 |
scale_points | integer | 7 | 每條兩極量表的檔位數(通常為 5 或 7) |
show_center_label | boolean | true | 是否在量表中點顯示 Neutral 標籤 |
label_requirement.required | boolean | false | 是否所有量表都必須評分才能繼續 |
示例
文本風格評估
yaml
annotation_schemes:
  - annotation_type: semantic_differential
    name: writing_style
    description: Rate the writing style of this text on each dimension.
    pairs:
      - ["Formal", "Informal"]
      - ["Objective", "Subjective"]
      - ["Concise", "Verbose"]
      - ["Clear", "Ambiguous"]
    scale_points: 7
說話人印象
yaml
annotation_schemes:
  - annotation_type: semantic_differential
    name: speaker_impression
    description: Rate your impression of the speaker on each dimension.
    pairs:
      - ["Competent", "Incompetent"]
      - ["Warm", "Cold"]
      - ["Trustworthy", "Untrustworthy"]
      - ["Dominant", "Submissive"]
    scale_points: 7
產品評價
yaml
annotation_schemes:
  - annotation_type: semantic_differential
    name: product_perception
    description: How do you perceive this product?
    pairs:
      - ["Innovative", "Traditional"]
      - ["Affordable", "Expensive"]
      - ["Reliable", "Unreliable"]
      - ["Simple", "Complex"]
    scale_points: 5
情感維度(EPA)
經典的評價-效力-活動(Evaluation-Potency-Activity)框架:
yaml
annotation_schemes:
  - annotation_type: semantic_differential
    name: epa_rating
    description: Rate this concept on each dimension.
    pairs:
      - ["Good", "Bad"]
      - ["Powerful", "Weak"]
      - ["Active", "Passive"]
    scale_points: 7
輸出格式
json
{
  "text_perception": {
    "labels": {
      "Formal-Informal": 5,
      "Positive-Negative": 2,
      "Simple-Complex": 4
    }
  }
}
取值從 1(左側形容詞)到 scale_points(右側形容詞),中點表示中立。
實踐建議
- 預設用 7 檔量表 —— 這是語義差異研究的通行做法,粒度也夠用
- 讓極性方向交錯 —— 把「正面」形容詞分散在左右兩側,避免標註者形成固定的作答模式
- 每個條目控制在 5 到 8 對 —— 量表太多會讓人疲勞,資料品質隨之下降
- 優先用現成的形容詞對 —— 已有研究中驗證過的形容詞對可以直接複用
- 保留中點標籤 —— 中立點是標註者重要的參照
- 打亂形容詞對的順序 —— 條件允許的話變換呈現順序,減少錨定效應
延伸閱讀
有關實現詳情,請參閱源文件。