用於 SFT/DPO 的軌跡編輯
標註者重寫智慧體軌跡中的步驟,以修正錯誤的推理步驟、糾正工具呼叫或強化最終答案,Potato 會將每個原始/修正對匯出為有監督微調目標和 DPO 偏好對。
trajectory_edit 模式讓標註者重寫智慧體軌跡中的步驟,並將每次修正匯出為訓練資料。 修正錯誤的推理步驟、糾正打錯字的工具呼叫,或強化最終答案,Potato 都會將修正後的軌跡儲存在原始軌跡旁邊。隨後 trajectory_correction 匯出器會將每個 (original, corrected) 對轉化為有監督微調(SFT)目標和直接偏好最佳化(DPO)偏好對。
這讓 Potato 不僅是一款評估工具,更成為一款訓練資料生產工具。它是步級評分的編輯對應物:標註者不是給軌跡打分,而是修復它,而修復本身就成為了一種學習訊號。
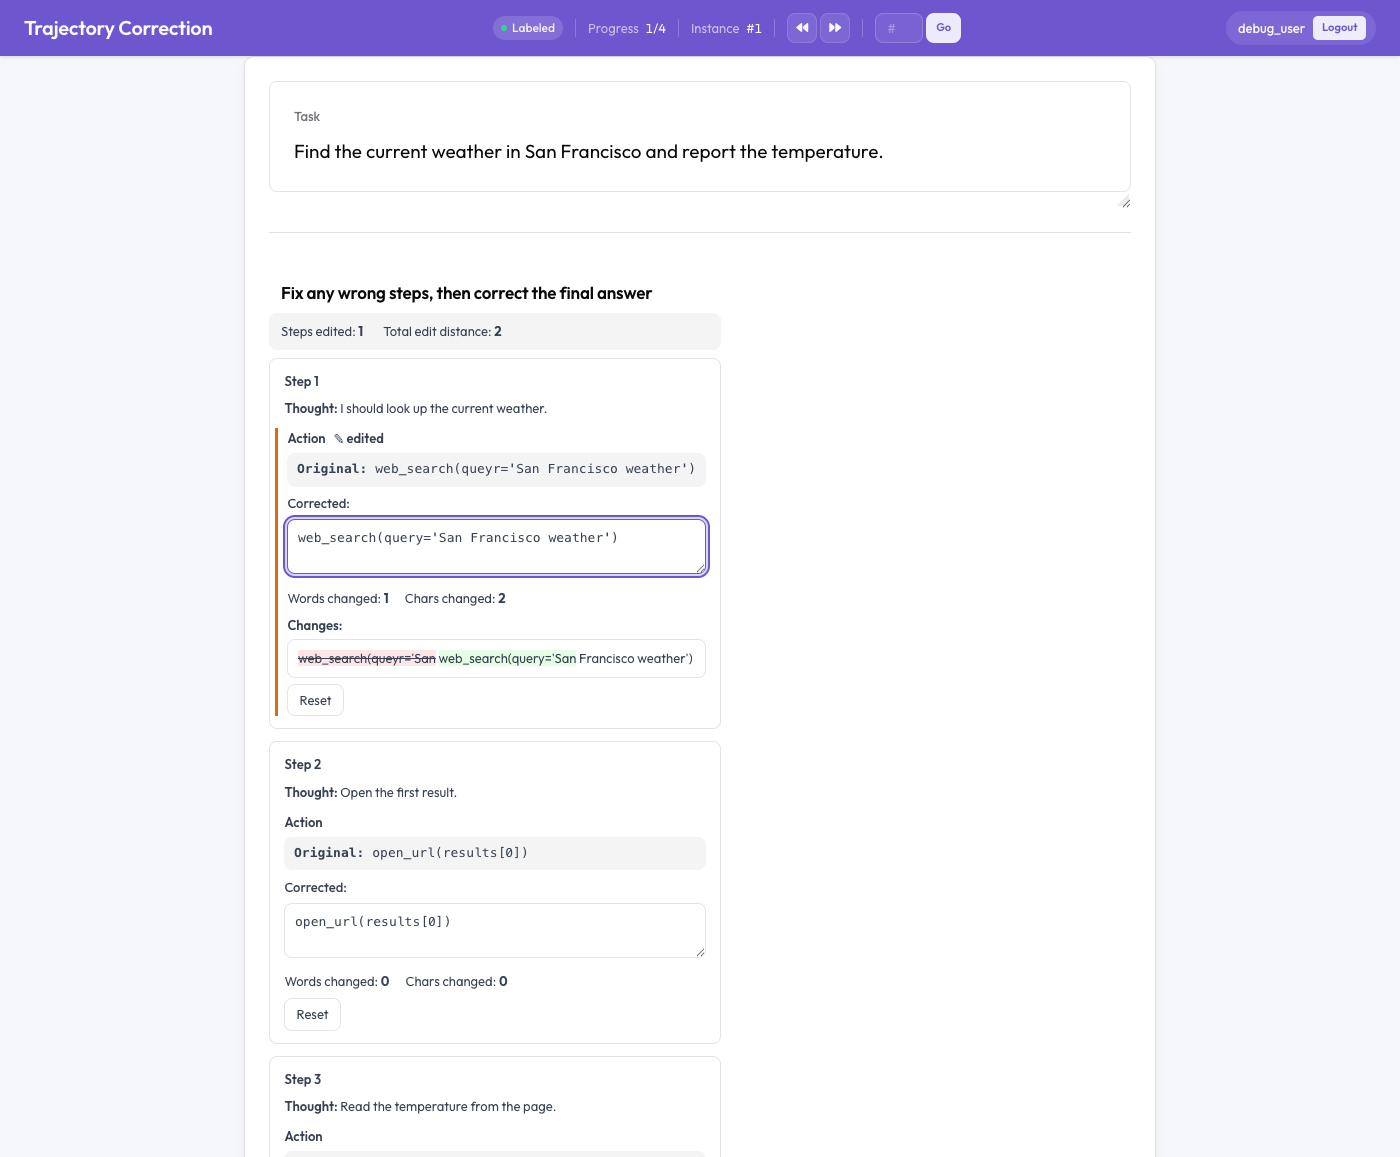 一個智慧體步驟,顯示一個只讀的原始內容和一個可編輯的修正框,並帶有詞級別的差異對比
快速開始
從倉庫根目錄執行隨附的示例:
python potato/flask_server.py start examples/agent-traces/trajectory-correction/config.yaml -p 8000工作原理
每個智慧體步驟都渲染為一張卡片,顯示原始文本(只讀)和一個預填了原始內容的可編輯修正框。當標註者輸入時:
- 即時的詞級別差異對比會高亮顯示插入內容(綠色)和刪除內容(紅色刪除線),
- 統計更改的詞數和字元數,以及
- 在已更改的欄位上出現"已編輯"標記。
"重置"按鈕可按欄位恢復原始內容。設定 edit_final_answer: true 後,最終答案會獲得自己的編輯器。一切都非必填:未經編輯的軌跡根本不會生成訓練對。
配置
annotation_schemes:
  - annotation_type: trajectory_edit
    name: corrected_trajectory
    description: "Fix any wrong steps, then correct the final answer"
    steps_key: steps          # instance field holding the step list
    step_text_key: action     # the default per-step editable field
    editable_fields:          # which fields get an editor
      - action
      # - thought             # add to also edit reasoning
    show_diff: true
    show_edit_distance: true
    allow_reset: true
    require_reason_on_edit: false   # add a per-field "reason" input
    edit_final_answer: true
final_answer_key: final_answer| 選項 | 預設值 | 描述 |
|---|---|---|
steps_key | steps | 儲存步驟列表的實例欄位。 |
step_text_key | action | 每個步驟預設的可編輯欄位。 |
editable_fields | [step_text_key] | 哪些步驟欄位獲得編輯器,例如 [action, thought]。 |
show_diff | true | 顯示即時的詞級別差異對比。 |
show_edit_distance | true | 顯示更改的詞數和字元數。 |
allow_reset | true | 每個欄位的"重置為原始"按鈕。 |
require_reason_on_edit | false | 每個欄位的"編輯原因"輸入框。 |
edit_final_answer | false | 為最終答案新增一個編輯器。 |
final_answer_key | final_answer | 儲存最終答案的實例欄位。 |
資料格式
該模式從實例的 steps_key 下讀取步驟。每個步驟都是一個物件,其欄位(action、thought 等)可被編輯;純字串步驟則作為 step_text_key 欄位進行編輯。
{
  "id": "traj_001",
  "task_description": "Find the weather in San Francisco.",
  "steps": [
    {"thought": "Look it up.", "action": "web_search(queyr='SF weather')"},
    {"thought": "Open it.",    "action": "open_url(results[0])"}
  ],
  "final_answer": "It is sunny."
}
匯出
執行 trajectory_correction 匯出器。它會寫入三個檔案:
trajectory_corrections.json— 包含每條記錄:original_trace、重建的corrected_trace,以及帶編輯距離和原因的逐欄位edits。trajectory_sft.jsonl— 每條已編輯軌跡一行:{"prompt": <task>, "completion": <corrected_trace>}。trajectory_dpo.jsonl— 每條已編輯軌跡一行:{"prompt": <task>, "chosen": <corrected_trace>, "rejected": <original_trace>}。
未編輯的軌跡會被計數但排除在 SFT/DPO 之外,因為在未更改的軌跡上訓練毫無意義;被跳過的數量會出現在匯出統計中。在多名標註者的情況下,每位編輯過某條軌跡的標註者都會產生一條 SFT/DPO 記錄。
注意事項與限制
- 差異對比是詞級別的。對於沒有空格、類似程式碼的工具呼叫,即使只改了一個字元,單個標記也可能顯示為整體更改;字元距離計數器才是精確的訊號。
- 如果你還想在同一條軌跡上獲得逐步正確性或錯誤分類,可搭配步級評分一起使用。
相關內容
有關實現細節,請參閱源文件。