觀察、暫停、回退:在 Potato 中即時觀察編碼智慧體
用 Ollama、Anthropic API 或 Claude Agent SDK 搭建即時編碼智慧體觀察的教程,涵蓋暫停、回滾、分支與軌跡匯出。
即時觀察不一樣在哪
編碼智慧體的評估大多發生在事後:智慧體跑完,留下一條 trace,評審者事後再對著錄影逐幀挑毛病。即時觀察反過來。標註者即時看著智慧體幹活,每一次檔案編輯、每一條終端命令、每一步推理落下來的時候就看見了。
這改變了你能做的事。如果智慧體開始往錯的方向走,標註者可以在它把時間浪費掉之前介入。可以先暫停,把 diff 仔細讀完再讓它繼續,也可以發一句大白話指令把它拉回來。我覺得最有用的是回滾:在之前任意一個檢查點上回退,讓智慧體換個思路重來。這些分支正是偏好學習需要的資料。
它並不取代靜態 trace 標註,它產出的是另一類資料。想以可預測的成本拿到大量資料時,靜態標註更合適;想要針對性的資料、想搞清楚一個智慧體是怎麼失敗的,或者想構造分支偏好對時,即時觀察更合適。
完整的功能參考見源文件。
即時編碼智慧體介面會即時推送智慧體的動作,邊幹邊顯示程式碼 diff 和終端輸出:
 即時編碼智慧體觀察,帶即時 diff 渲染和終端輸出
三種後端
Potato 為即時觀察提供三種後端。每一種都在沙箱裡執行一個編碼智慧體,並把它的動作即時推送到介面。
Ollama(完全本地)
Ollama 後端完全跑在你自己的機器上,不需要 API key,也不髮網絡請求。程式碼庫比較敏感,或者你只是想試試水而不想燒 API 賬單時,用它。
先安裝 Ollama,拉一個具備工具呼叫能力的模型:
# Install Ollama
curl -fsSL https://ollama.ai/install.sh | sh

# Pull a coding-capable model
ollama pull qwen2.5-coder:32b

# Verify the model is available
ollama list
把 Potato 配置成使用 Ollama 後端:
# config.yaml
annotation_task_name: "Live Agent Observation - Ollama"
port: 8000

live_coding_agent:
  backend_type: ollama_tool_use
  ai_config:
    model: "qwen2.5-coder:32b"
    base_url: "http://localhost:11434"
    temperature: 0.2
    max_tokens: 4096
  working_dir: ./workspace       # Agent's working directory
  max_turns: 50
  sandbox_mode: container        # container (default) | bubblewrap | trusted
  sandbox_image: "python:3.11-slim"
Anthropic API(帶工具呼叫的 Claude)
Anthropic API 後端連的是支援工具呼叫的 Claude 模型。推理和程式碼生成比大多數本地模型強,代價是 API 呼叫要花錢。
# Set your API key
export ANTHROPIC_API_KEY="sk-ant-..."# config.yaml
annotation_task_name: "Live Agent Observation - Claude"
port: 8000
live_coding_agent:
backend_type: anthropic_tool_use
ai_config:
model: "claude-sonnet-4-20250514"
max_tokens: 8192
temperature: 0.1
system_prompt: >
You are a coding agent. You will be given a task description and
access to a codebase. Use the provided tools to read files, make
edits, and run commands to complete the task. Think step by step
and verify your changes by running tests.
working_dir: ./workspace
max_turns: 50
sandbox_mode: container
sandbox_image: "python:3.11-slim"Claude Agent SDK(完整的 Claude Code 能力)
Claude Agent SDK 後端是三者中能力最強的,帶完整的 Claude Code 工具集和自主行為。它需要 claude-agent-sdk 包。
# Install the Claude Agent SDK
pip install claude-agent-sdk# config.yaml
annotation_task_name: "Live Agent Observation - Claude Agent SDK"
port: 8000
live_coding_agent:
backend_type: claude_sdk
ai_config:
model: "claude-sonnet-4-20250514"
working_dir: ./workspace
max_turns: 50 # Maximum number of agent turns
sandbox_mode: container
sandbox_image: "node:20-slim"標註流程
服務起來之後,一次即時觀察會話會經過幾個階段。
開始一次會話
標註者開啟 Potato 介面,看到一個任務描述輸入框。他們把要交給智慧體的任務貼上或敲進去,比如"修復 tests/test_parser.py 中因新配置格式導致失敗的測試"或者"給 /api/users 介面加上分頁支援"。
# Start the server
potato start config.yaml -p 8000
標註者點選 "Start Agent",編碼智慧體開始幹活。每一個動作都會即時出現在 CodingTraceDisplay 面板裡。
看著智慧體工作
智慧體執行時,每一步都會出現在 trace 檢視中:
- 思考步驟顯示為可摺疊的灰色塊,展示智慧體的推理。
- 檔案讀取顯示為帶語法高亮的程式碼塊,附行號和檔案路徑。
- 檔案編輯顯示為 unified diff,用紅綠高亮。
- 終端命令顯示為深色終端塊,包含命令、輸出和退出碼。
- 檔案樹在側邊欄隨檔案的建立、修改、讀取而更新。
頂部的進度指示顯示當前步數和已用時間。智慧體的狀態會顯示為 "Thinking..."、"Editing file..."、"Running command..." 等。
暫停與指令控制
智慧體執行期間,標註者可以通過控制欄介入:
Pause:在當前這一步做完之後凍結智慧體。恢復之前它不會進入下一步。想在智慧體往下走之前仔細看一段 diff 或終端輸出時用它。
Send Instruction:在暫停期間(甚至執行過程中)輸入一段自然語言訊息,注入到智慧體的上下文裡。例如:"不要改資料庫 schema,用 migration"或者"改動之前先看看 /var/log/app.log 裡的錯誤日誌"。
Resume:暫停後繼續執行。
Stop:直接結束這次智慧體會話。到此為止的軌跡會被儲存。
標註者可以在 trace 顯示旁邊用 PRM 標註來評價智慧體的工作:
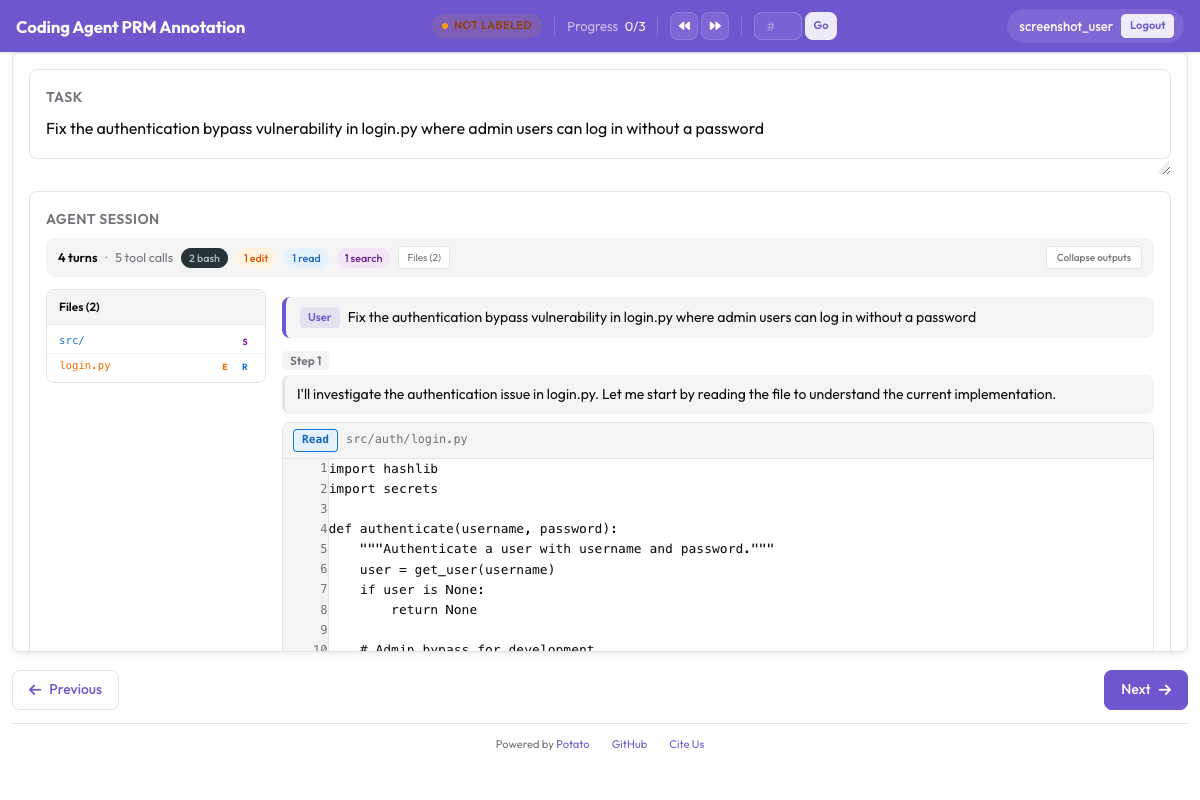 PRM 標註介面,在編碼 trace 旁做步驟級正確性標註
控制欄是即時編碼智慧體檢視器自帶的。暫停、恢復、注入指令、停止、回滾和切換分支都是介面通過即時智慧體介面發起的會話操作,配置裡沒有什麼需要開啟的開關。
基於 git 的檢查點系統
回滾、分支和軌跡匯出全都建立在檢查點系統之上,而這個系統的做法是在智慧體每次改動檔案之後提交一次 git。
工作方式
會話開始時,Potato 在沙箱工作區裡初始化一個 git 倉庫,或者直接用已有的那個。每次檔案編輯之後自動提交,提交資訊是結構化的:
[potato-checkpoint] Step 7: Edit src/parser.py
- Modified lines 45-52
- Agent reasoning: Fix the regex pattern to handle escaped quotes
結果是一條線性的提交歷史,和軌跡中的步驟一一對應。每個檢查點儲存了那一刻工作區的完整狀態。
# You can inspect checkpoints directly with git
cd workspace/
git log --oneline

# Output:
# f8a2c1d [potato-checkpoint] Step 12: Edit tests/test_parser.py
# 3b7e9f0 [potato-checkpoint] Step 10: Edit src/parser.py
# a1c4d8e [potato-checkpoint] Step 8: Edit src/parser.py
# 9e2f6b3 [potato-checkpoint] Step 5: Edit src/config.py
# 7d0a3c1 [potato-checkpoint] Step 0: Initial state
回滾
點選 "Rollback",從下拉式清單裡挑一個更早的檢查點。Potato 用 git checkout 把工作區重置到那個狀態,軌跡顯示也一起回退,然後智慧體從那裡繼續,上下文被裁剪回那一步。
智慧體走錯路的時候就該用它。與其看著它繼續燒時間,不如回到上一個好狀態讓它重來,也可以順手給一條指令把它引到更好的方向。
分支軌跡
分支就是保留兩條路徑的回滾。你回滾之後智慧體換了走法,Potato 會建立一個命名的 git 分支,同時跟蹤兩條軌跡:
Step 0 → Step 1 → Step 2 → Step 3 → Step 4 (Branch A: original path)
                          ↘
                           Step 3' → Step 4' → Step 5' (Branch B: after rollback)
你可以從任意檢查點分支,逐漸長出一整棵軌跡樹。這對偏好學習很有用,因為每一對分支本身就是一次已標註的比較:你之所以回滾,正是因為判定分支 A 走錯了,那麼從分支點往後,分支 B 就是被偏好的那條路。
分支同樣不需要配置。你回滾之後智慧體走了另一條路,Potato 就把分支建出來,並在這次會話剩下的時間裡同時跟蹤兩條軌跡。
匯出格式
一次即時會話會產出詳細的軌跡資料,你可以按訓練目標匯出成幾種不同的形態。
線性軌跡匯出
把每條分支匯出為獨立的軌跡:
python -m potato.export \
  -c config.yaml \
  -f trajectory_correction \
-o ./training_data/{
"session_id": "session_001",
"branch": "branch-A",
"task": "Fix the failing test in tests/test_parser.py",
"steps": [
{"step_idx": 0, "type": "file_read", "path": "tests/test_parser.py", "...": "..."},
{"step_idx": 1, "type": "thinking", "content": "The test expects..."},
{"step_idx": 2, "type": "file_edit", "path": "src/parser.py", "diff": "..."},
{"step_idx": 3, "type": "bash_command", "command": "pytest tests/test_parser.py"}
],
"human_interventions": [
{"after_step": 2, "type": "instruction", "content": "Use a migration instead"}
],
"rollback_from_step": null,
"outcome": "resolved"
}從分支得到偏好對
把分支對匯出為 DPO 或 RLHF 用的偏好資料:
python -m potato.export \
  -c config.yaml \
  -f trajectory_correction \
-o ./training_data/{
"session_id": "session_001",
"task": "Fix the failing test in tests/test_parser.py",
"branch_point_step": 2,
"branch_point_reason": "Agent started modifying the wrong file",
"rejected_branch": "branch-A",
"rejected_steps": [
{"step_idx": 3, "type": "file_edit", "path": "src/wrong_file.py", "...": "..."},
{"step_idx": 4, "type": "bash_command", "command": "pytest", "exit_code": 1}
],
"chosen_branch": "branch-B",
"chosen_steps": [
{"step_idx": 3, "type": "file_edit", "path": "src/parser.py", "...": "..."},
{"step_idx": 4, "type": "bash_command", "command": "pytest", "exit_code": 0}
]
}從即時觀察得到 PRM 標籤
即時觀察可以和 PRM 標註配合,因為回滾點通常就是第一個出錯的步驟:
python -m potato.export \
  -c config.yaml \
  -f coding_eval \
  -o ./training_data/ \
  --option types=prm
這裡被你回滾掉的那一步會被標為首個錯誤,新分支上的步驟則標為正確,因為你接受了它們。
程式碼評審資料集
把標註者的指令和回滾理由匯出為程式碼評審訓練資料:
python -m potato.export \
  -c config.yaml \
  -f coding_eval \
  -o ./training_data/ \
  --option types=code_review
完整快速上手
從零到跑起一個 Ollama 會話的全部步驟:
# 1. Install Potato with live agent support
pip install potato-annotation[live-agents]

# 2. Install and start Ollama
curl -fsSL https://ollama.ai/install.sh | sh
ollama pull qwen2.5-coder:32b

# 3. Set up a workspace with a repo to work on
mkdir -p workspace/
git clone https://github.com/example/test-project workspace/repo

# 4. Create the config file
cat > config.yaml << 'YAML'
annotation_task_name: "Live Agent Observation"
port: 8000

live_coding_agent:
  backend_type: ollama_tool_use
  ai_config:
    model: "qwen2.5-coder:32b"
    base_url: "http://localhost:11434"
    temperature: 0.2
  working_dir: ./workspace/repo
  max_turns: 50
  sandbox_mode: trusted

annotation_schemes:
  - annotation_type: radio
    name: outcome
    description: "Final outcome"
    labels:
      - name: "resolved"
        text: "Task Fully Resolved"
      - name: "partial"
        text: "Partially Resolved"
      - name: "failed"
        text: "Failed"

  - annotation_type: text
    name: notes
    description: "Session Notes"
    placeholder: "Key observations about agent behavior..."
    label_requirement:
      required: false

output_annotation_dir: "./output/"
export_annotation_format: jsonl

user_config:
  allow_all_users: false
  users:
    - "observer1"
YAML

# 5. Start Potato
potato start config.yaml -p 8000

# 6. Open http://localhost:8000 in your browser
登入之後,貼上一個任務,比如"給 /api/users 的 POST 介面加上輸入校驗",然後點 "Start Agent"。看著它幹活,覺得不對就暫停,發指令把它引開,回滾去試別的做法。做完之後給結果打分,記下筆記。
實踐建議
任務要清晰、有邊界。 最合適的是讓智慧體做 5 到 15 分鐘的活。再短,產出的軌跡不夠長,不值得標註;長太多,標註者會累。
生產環境用 Docker 沙箱。 開發階段用本地沙箱模式沒問題,但 Docker 能擋住智慧體去動你的宿主機。面對不可信的模型時一定要用。
記錄回滾理由。 開啟 require_reason_on_rollback,讓每個分支點都帶上一條人寫的說明,講清楚哪裡出了問題。這些說明本身就是有用的訓練訊號,也讓偏好資料品質更好。
多後端對比。 同一批任務分別用 Ollama、Anthropic API 和 Claude Agent SDK 跑一遍,就能拿到跨智慧體的偏好資料。配置裡只有 backend 那一段要改,很好搭。
早匯出、勤匯出。 每次會話結束就導一次,別攢到最後。崩了損失小,也能一路盯著資料品質。