語音情感分類
在 Potato 中建立音訊情感分類任務,配有互動式波形顯示、播放速度控制、李克特量表和可配置的情感標籤集。
語音情感識別(SER)出現在虛擬助手、心理健康工具和呼叫中心分析裡,而這些都需要帶標籤的音訊來訓練。本教程會走一遍分類式情感、維度評分,以及包含不止一種情感的片段各自適用的標註介面。音訊的底層選項請參閱音訊標註文件。
情感標註方法
標註語音情感有幾種常見做法。你可以使用快樂、悲傷、憤怒這樣的離散類別。你可以在效價、喚醒度和支配度這類連續維度上打分。你可以讓標註者一次標出多種情感並給出強度評分。或者,對於較長的片段,在不同時間戳上標註不同的情感。
分類式情感分類
基本配置
annotation_task_name: "Speech Emotion Recognition"

data_files:
  - data/utterances.json

item_properties:
  id_key: id
  text_key: transcript  # Optional transcript

instance_display:
  fields:
    - key: audio_path
      type: audio
      label: "Utterance"
      display_options:
        controls: true
        show_waveform: true
        preload: metadata

annotation_schemes:
  - annotation_type: radio
    name: emotion
    description: "What emotion is expressed in this speech?"
    labels:
      - name: Happy
        description: "Joy, excitement, amusement"
        key_value: "h"
      - name: Sad
        description: "Sorrow, disappointment, grief"
        key_value: "s"
      - name: Angry
        description: "Frustration, irritation, rage"
        key_value: "a"
      - name: Fearful
        description: "Anxiety, worry, terror"
        key_value: "f"
      - name: Surprised
        description: "Astonishment, shock"
        key_value: "u"
      - name: Disgusted
        description: "Revulsion, distaste"
        key_value: "d"
      - name: Neutral
        description: "No clear emotion"
        key_value: "n"
    label_requirement:
      required: true
Potato 會在標註標籤旁渲染一個帶播放控制元件的互動式波形:
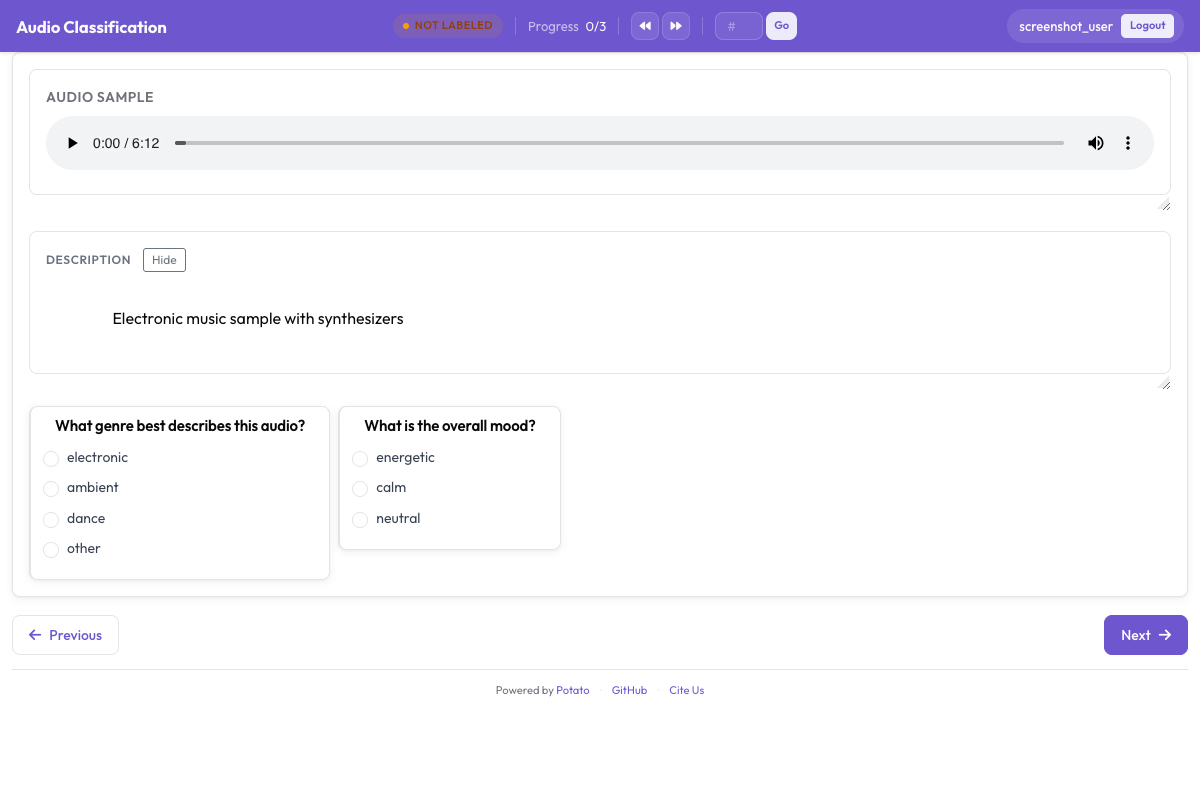 音訊標註介面,顯示帶播放控制元件的互動式波形和分類式情感標籤
新增強度評分
annotation_schemes:
  - annotation_type: radio
    name: emotion
    description: "What emotion does the speaker express?"
    labels: [Happy, Sad, Angry, Fearful, Surprised, Disgusted, Neutral]
    label_requirement:
      required: true

  - annotation_type: likert
    name: intensity
    description: "How intense is this emotion?"
    size: 5
    min_label: "Very weak"
    max_label: "Very strong"
維度式情感標註
VAD(效價-喚醒度-支配度)模型不會強行把片段塞進某一個類別,而是在三個連續量表上分別給它打分:
annotation_task_name: "Dimensional Emotion Rating"

annotation_schemes:
  # Valence: negative to positive
  - annotation_type: likert
    name: valence
    description: "Valence: How positive or negative?"
    size: 7
    min_label: "Very negative"
    max_label: "Very positive"

  # Arousal: calm to excited
  - annotation_type: likert
    name: arousal
    description: "Arousal: How calm or excited?"
    size: 7
    min_label: "Very calm"
    max_label: "Very excited"

  # Dominance: submissive to dominant
  - annotation_type: likert
    name: dominance
    description: "Dominance: How submissive or dominant?"
    size: 7
    min_label: "Very submissive"
    max_label: "Very dominant"
視覺量表 (SAM)
自我評估人偶(Self-Assessment Manikin)風格:
annotation_schemes:
  - annotation_type: likert
    min_label: "Very negative"
    max_label: "Very positive"
    name: valence
    description: "Select the figure that matches the emotional valence"
    size: 9
混合情感檢測
對於包含多種情感的語音:
annotation_schemes:
  - annotation_type: multiselect
    name: emotions_present
    description: "Select ALL emotions you detect (can be multiple)"
    labels:
      - Happy
      - Sad
      - Angry
      - Fearful
      - Surprised
      - Disgusted
      - Contempt

  - annotation_type: radio
    name: primary_emotion
    description: "Which emotion is MOST prominent?"
    labels:
      - Happy
      - Sad
      - Angry
      - Fearful
      - Surprised
      - Disgusted
      - Contempt
      - Mixed (no dominant)
完整的情感標註
annotation_task_name: "Comprehensive Speech Emotion Annotation"

data_files:
  - data/speech_samples.json

item_properties:
  id_key: id
  text_key: transcript

instance_display:
  fields:
    - key: audio_url
      type: audio
      label: "Speech sample"
      display_options:
        controls: true
        show_waveform: true
        preload: metadata
        autoplay: false

    # Show the transcript alongside the audio
    - key: transcript
      type: text
      label: "Transcript (for reference)"

annotation_schemes:
  # Primary categorical emotion
  - annotation_type: radio
    name: primary_emotion
    description: "Primary emotion expressed"
    labels:
      - name: Happiness
        color: "#FCD34D"
        key_value: "1"
      - name: Sadness
        color: "#60A5FA"
        key_value: "2"
      - name: Anger
        color: "#F87171"
        key_value: "3"
      - name: Fear
        color: "#A78BFA"
        key_value: "4"
      - name: Surprise
        color: "#34D399"
        key_value: "5"
      - name: Disgust
        color: "#FB923C"
        key_value: "6"
      - name: Neutral
        color: "#9CA3AF"
        key_value: "7"
    label_requirement:
      required: true

  # Emotional intensity
  - annotation_type: likert
    name: intensity
    description: "Emotional intensity"
    size: 5
    min_label: "Very mild"
    max_label: "Very intense"
    label_requirement:
      required: true

  # Dimensional ratings
  - annotation_type: likert
    name: valence
    description: "Valence (negative to positive)"
    size: 7
    min_label: "Negative"
    max_label: "Positive"

  - annotation_type: likert
    name: arousal
    description: "Arousal (calm to excited)"
    size: 7
    min_label: "Calm"
    max_label: "Excited"

  # Voice quality
  - annotation_type: multiselect
    name: voice_qualities
    description: "Voice characteristics (select all that apply)"
    labels:
      - Trembling voice
      - Raised pitch
      - Lowered pitch
      - Loud/shouting
      - Soft/whisper
      - Fast speech rate
      - Slow speech rate
      - Breathy
      - Tense/strained
      - Crying
      - Laughing

  # Genuineness
  - annotation_type: radio
    name: authenticity
    description: "Does the emotion seem genuine?"
    labels:
      - Clearly genuine
      - Likely genuine
      - Uncertain
      - Likely acted/fake
      - Clearly acted/fake

  # Confidence
  - annotation_type: likert
    name: confidence
    description: "How confident are you in your annotation?"
    size: 5
    min_label: "Guessing"
    max_label: "Certain"

annotation_instructions: |
  ## Emotion Annotation Guidelines

  ### Listening Instructions
  1. Listen to the entire clip before annotating
  2. You may replay as many times as needed
  3. Focus on the VOICE, not just the words

  ### Emotion Categories
  - **Happiness**: Joy, amusement, contentment
  - **Sadness**: Sorrow, disappointment, melancholy
  - **Anger**: Frustration, irritation, rage
  - **Fear**: Anxiety, nervousness, terror
  - **Surprise**: Astonishment, startle
  - **Disgust**: Revulsion, contempt
  - **Neutral**: Calm, matter-of-fact

  ### Tips
  - Consider tone, pitch, speaking rate
  - The transcript may not match the emotion
  - When unsure between two emotions, choose the stronger one
  - Use the intensity scale for unclear cases

output_annotation_dir: annotations/
export_annotation_format: jsonl
輸出格式
{
  "instance_id": "utt_001",
  "user_id": "rater_01",
  "labels": {
    "primary_emotion": {"Surprise": "true"},
    "voice_qualities": {"Raised pitch": "true", "Fast speech rate": "true"},
    "authenticity": {"Clearly genuine": "true"},
    "confidence": {"4": "true"}
  },
  "spans": {},
  "links": {}
}
片段級情感標註
對於情感會發生變化的較長音訊:
annotation_schemes:
  - annotation_type: audio_annotation
    name: emotion_segments
    description: "Mark time segments with different emotions"
    labels:
      - name: Happy
        color: "#FCD34D"
      - name: Sad
        color: "#60A5FA"
      - name: Angry
        color: "#F87171"
      - name: Neutral
        color: "#9CA3AF"
品質控制
標籤已知、不存在歧義的片段可以抓出那些一路亂點的標註者。這兩個配置塊都位於配置的頂層,而且都從檔案讀取條目,不是內聯寫死的:
attention_checks:
  enabled: true
  frequency: 20
  items_file: data/attention_checks.json
  min_response_time: 3.0

gold_standards:
  enabled: true
  items_file: data/gold_standards.json
  mode: mixed
  frequency: 20
  accuracy:
    min_threshold: 0.7
    evaluation_count: 10
一個 gold 條目就是你的普通資料條目加上一個 gold_label,所以它的渲染方式和其他條目完全一樣:
[
  {
    "id": "gold_001",
    "audio_path": "/audio/gold/clearly_happy.wav",
    "gold_label": { "primary_emotion": "Happiness" },
    "explanation": "Laughter and rising pitch throughout, with no ambiguity.",
    "difficulty": "easy"
  }
]
注意力檢查條目用 expected_answer 代替 gold_label。對音訊任務來說,min_response_time 是最有用的那個控制項:三秒的下限能抓出那些不可能聽完就給片段打標籤的人。
把這兩塊嵌進 quality_control: 裡是個常見錯誤,而且它不會報錯。Potato 從頂層讀取 attention_checks 和 gold_standards,而它從 quality_control 讀取的鍵只有 geometry_iou_tolerance,所以巢狀寫法能通過校驗,卻從不生效。
情感標註技巧
先完整聽完片段再下判斷,並且注意的是話怎麼說,而不是說了什麼。要記得表達規範因文化而異,在一種文化裡聽起來像憤怒的,在另一種文化裡可能只是強調。情感標註很耗精力,所以鼓勵大家適時休息,並讓團隊定期討論分歧,以保持校準一致。
下一步
文件請參閱 音訊標註。