構建你的第一個命名實體識別標註任務
逐步搭建 Potato 中的命名實體識別任務:span 標註配置、標籤顏色、重疊片段、鍵盤快捷鍵和 CoNLL 匯出。
本教程在 Potato 中構建一個命名實體識別(NER)任務,包含五種實體類型、數字鍵快捷鍵、標註者指南,以及用於模型訓練的 CoNLL-2003 匯出。其背後的 span 配置選項,見 span 標註文件。
標註者看到的介面
任務建好後,標註者看到的是一個句子,上方是一排標籤按鈕。拖動滑鼠選中一個短語,按數字鍵或點選按鈕給它打上標籤,再次點選已標註的片段就能修改或刪除。每個片段都連同它的字元偏移量一起儲存,所以同一份標註檔案既能匯出成 CoNLL-2003,也能用來計算片段級別的一致性。
前置條件
你需要裝好 Potato、一份文本資料檔案,以及夠用的 YAML 基礎來改配置:
pip install potato-annotation第 1 步:span 方案
片段標註用的是 Potato 的 span 類型。每個標籤都要有名稱,此外有幾個好用的可選欄位:color 在密集文本上把不同實體類型區分開,key_value 把一個鍵盤快捷鍵綁到標籤上,tooltip 在滑鼠懸停時顯示標籤的定義,標註者不用離開頁面去翻編碼手冊。
五種類型能讓標註者一次坐下就把任務學會。超過八種左右,標註者就會在每條資料上都去查指南,效率正是在這裡掉下來的。sequential_key_binding 啟用數字鍵,key_value 指定哪個數字對應哪個標籤,而不是聽憑列表順序決定。建立 config.yaml:
annotation_task_name: "Named Entity Recognition"
task_dir: "."

data_files:
  - data/sentences.json

item_properties:
  id_key: id
  text_key: text

output_annotation_dir: "annotation_output/"
export_annotation_format: "jsonl"

annotation_schemes:
  - annotation_type: span
    name: entities
    description: "Highlight and label named entities in the text"
    sequential_key_binding: true
    labels:
      - name: PER
        tooltip: "Person names, including fictional characters"
        color: "#FF6B6B"
        key_value: "1"
      - name: ORG
        tooltip: "Companies, institutions, agencies"
        color: "#4ECDC4"
        key_value: "2"
      - name: LOC
        tooltip: "Places, including countries, cities, landmarks"
        color: "#45B7D1"
        key_value: "3"
      - name: DATE
        tooltip: "Dates, times, and temporal expressions"
        color: "#96CEB4"
        key_value: "4"
      - name: MISC
        tooltip: "Named entities that fit none of the above"
        color: "#FFEAA7"
        key_value: "5"

user_config:
  allow_all_users: true
第 2 步:資料檔案
Potato 按行讀取 JSON 物件,取用 item_properties 中指定的欄位。建立 data/sentences.json:
{"id": "1", "text": "Apple Inc. announced that CEO Tim Cook will visit Paris next Tuesday."}
{"id": "2", "text": "The United Nations headquarters in New York hosted delegates from Japan."}
{"id": "3", "text": "Dr. Sarah Johnson published her research at Stanford University in March 2024."}
三個句子足夠檢驗介面是否正常。等標籤集通過了試標註,再載入真正的語料。
第 3 步:標註者隨手可及的指南
NER 的分歧大多來自邊界規則,而不是實體類型本身,所以決定條目最多的那幾條規則應該放在標註介面上。annotation_instructions 會在每條資料頂部渲染成一個可摺疊面板,預設展開,標註者熟悉任務後可以把它收起來。把下面這段加進上面的配置:
annotation_instructions: |
  ## Entity types

  - **PER** covers people, including fictional characters ("John Smith", "Dr. Johnson", "Batman")
  - **ORG** covers companies, institutions, and agencies ("Apple Inc.", "United Nations", "Stanford University")
  - **LOC** covers places, including countries, cities, and landmarks ("Paris", "New York", "Mount Everest")
  - **DATE** covers dates, times, and temporal expressions ("Tuesday", "March 2024", "next week")
  - **MISC** covers named entities that fit none of the above ("Nobel Prize", "iPhone", "COVID-19")

  ## Boundary rules

  1. Include titles (Dr., Mr.) with person names.
  2. For nested entities, annotate the largest meaningful span.
  3. Leave articles (the, a) outside the span.
這裡支援 Markdown,所以可以直接把編碼手冊裡的文字搬過來,不用改寫成 HTML。這個面板只留能定下大多數條目的規則,完整的編碼手冊交給 annotation_codebook_url,它會在單獨的標籤頁裡開啟。
片段標註介面會把標籤顯示為文本上方的按鈕:
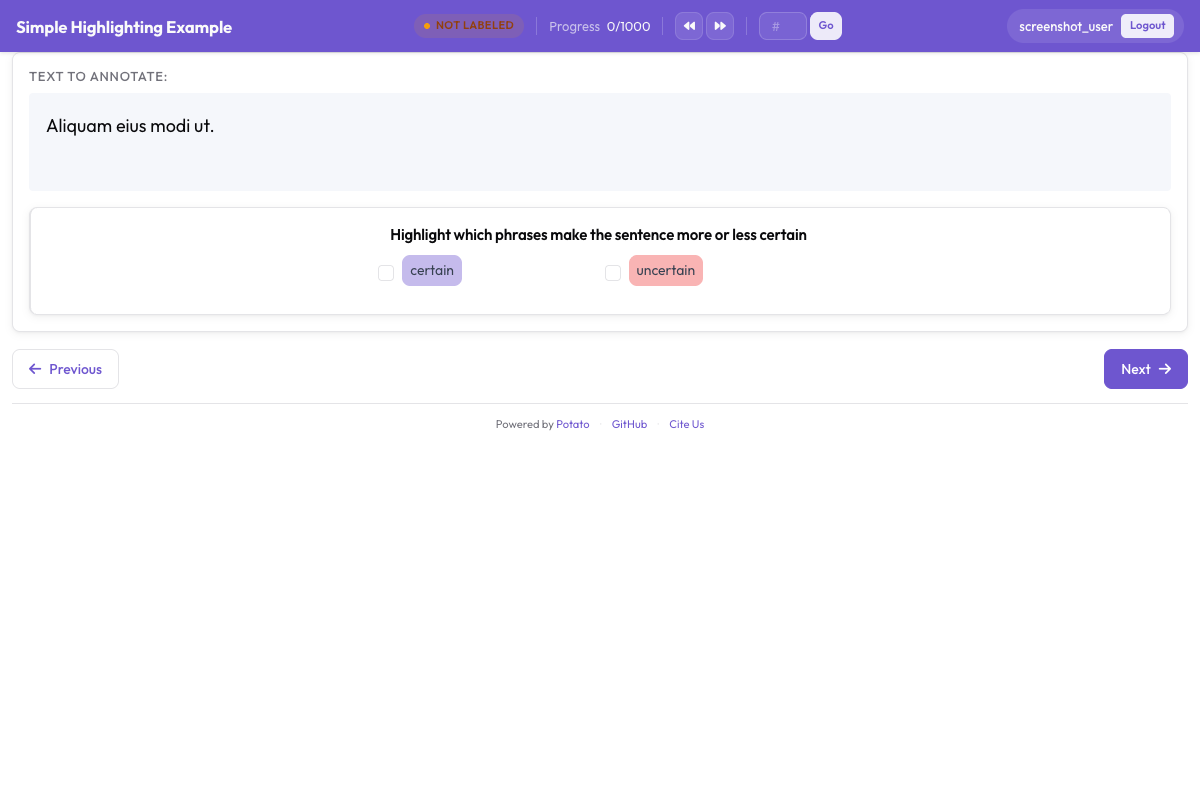 標註者高亮文本片段並指定 PER、ORG、LOC、DATE 等實體標籤
第 4 步:執行任務
用第 1 步的配置啟動伺服器:
potato start config.yaml開啟它打印出的地址並登入。標註者對每個實體走四步:
- 選中文本。 點選並拖過這個短語。
- 指定類型。 按數字鍵或點選標籤按鈕。
- 改正錯誤。 點選已有的片段來改標籤或刪掉它。
- 提交。 這個句子做完就進入下一條。
第 5 步:輸出檔案裡有什麼
每條標註完的資料會作為一個 JSON 物件寫入 annotation_output/,以方案名作為鍵,每個片段一條記錄:
{
  "id": "1",
  "text": "Apple Inc. announced that CEO Tim Cook will visit Paris next Tuesday.",
  "entities": [
    {"start": 0, "end": 10, "label": "ORG", "text": "Apple Inc."},
    {"start": 30, "end": 38, "label": "PER", "text": "Tim Cook"},
    {"start": 50, "end": 55, "label": "LOC", "text": "Paris"},
    {"start": 61, "end": 73, "label": "DATE", "text": "next Tuesday"}
  ]
}
字元偏移量是這份檔案在下游有用的原因。它們不受分詞方式變化的影響,所以同一批標註可以重新對齊到模型使用的任何分詞器。
第 6 步:匯出為 CoNLL-2003
序列標註模型讀的是帶標籤的 token,而不是字元偏移量,所以 Potato 在匯出時會轉換這些片段:
python -m potato.export -c config.yaml -f conll_2003 -o ./conll_export/結果是每行一個 token 加它的標籤,句子之間用空行隔開。tag_scheme 選項可以寫 BIO、BIOES 或 IOB,預設是 BIO,匯出之前先把它調成訓練程式碼期望的那一種。
收緊標註指南
規則含糊,同一個片段就會被判成不同結果,所以趁試標註規模還小的時候修訂規則最划算。帶標註者過一遍難例要放在他們開工之前,而不是之後,邊緣案例一旦有了定論就隨手記進一份共享清單。標註者之間的一致性下滑,就是某條規則該收緊的訊號,在 50 條資料上發現這一點,比在 5000 條上便宜得多。
下一步
- 新增訓練階段,讓標註者在接觸真實資料之前先上手
- 設定多標註者,這樣片段標註之間可以互相比較
- 匯出為 Hugging Face 格式用於模型訓練
- 閱讀 span 標註文件瞭解完整的選項列表