Модели принятия решений как дешёвый первый уровень разметки
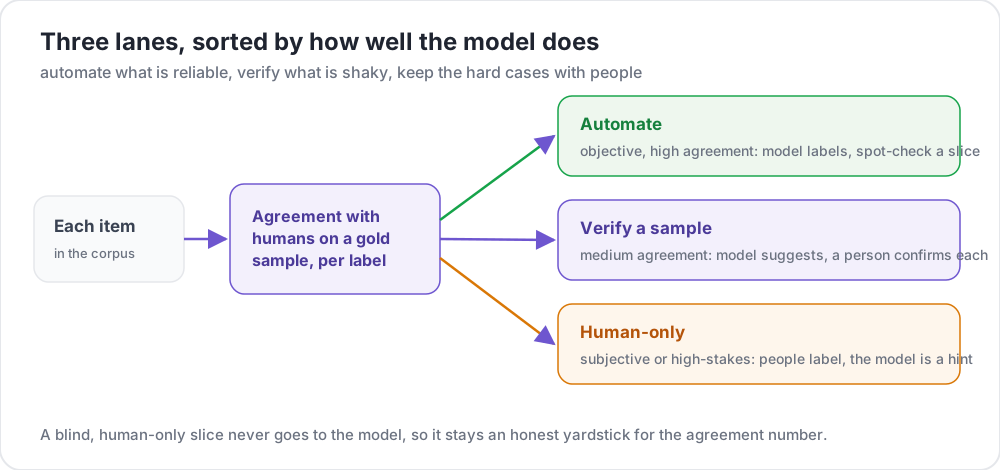
Модель принятия решений оценивает все варианты за один прямой проход без генерации текста. Это первый уровень разметки перед LLM для вопросов с немногими вариантами.
Новости, руководства и обновления от команды Potato.
Модель принятия решений оценивает все варианты за один прямой проход без генерации текста. Это первый уровень разметки перед LLM для вопросов с немногими вариантами.
Шесть инструментов разметки: как метки моделей и LLM попадают в проект, как люди их проверяют и что каждый инструмент сообщает о доле ошибок в машинных метках.
Label Studio, CVAT, doccano, Argilla, INCEpTION и Potato: сервисы, база данных, вход и резервные копии при установке на свой сервер, а также хостинги по цене.
Получайте уведомления о новых туториалах, релизах и новостях сообщества.
Many robot episodes end in partial success, and binary labels discard it. Annotation needs a timeline, min/max downsampling, and relabeling.
Click-to-segment and text prompting run in the browser with no GPU, using a verified encoder contract, a measured quantization, and a hand-written tokenizer.
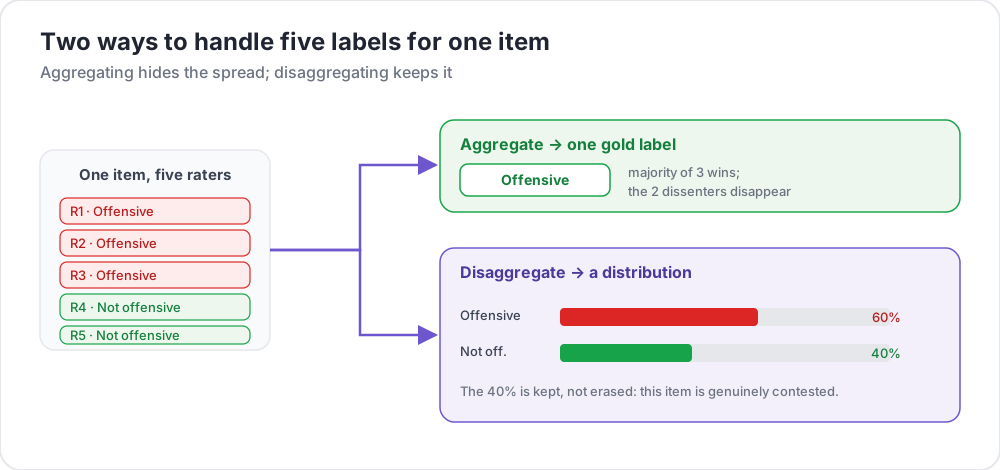
An LLM judge is only as trustworthy as the human labels it was checked against. Give those labels intervals, and compare human and model reasoning per item.
Potato 2.7.1 reads 21 transcript and subtitle formats, loads them from sidecar files next to your media, and converts a folder of ASR output to a data file.


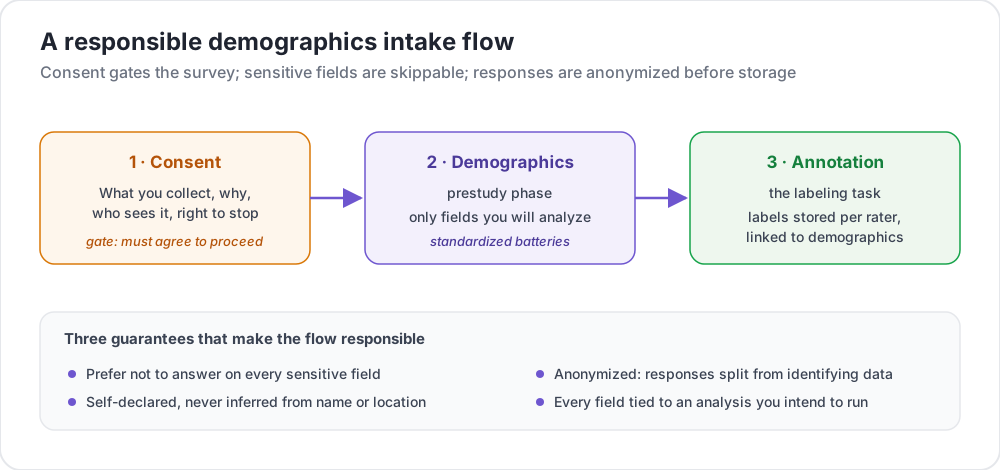
When who annotates matters, use a validated questionnaire rather than one you invented. Potato ships 55 survey instruments for prestudy and poststudy phases.
Record the curation rationale, annotator pool, guidelines, and intended use when you release an annotation dataset, and see how much of it Potato captures.


Potato 2.6 is out: QDA Mode for qualitative coding, an LLM-as-judge calibration and alignment workflow, trajectory editing that produces SFT and DPO training data, a 3x faster boot, and a relicense to GPL-3.0-or-later.
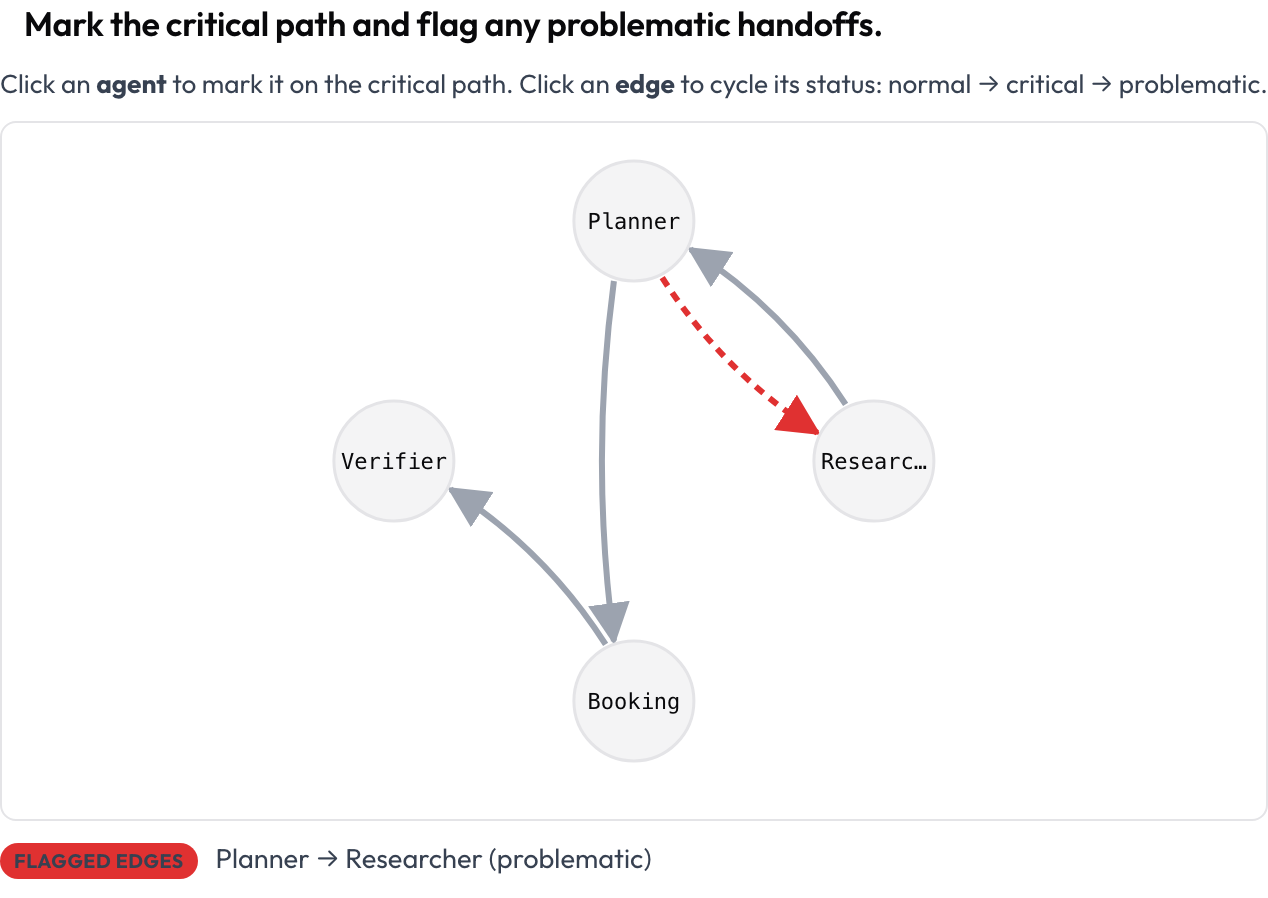
Линейка 2.6.x превращает Potato в полноценную бесплатную платформу оценки агентов: приём трасс из OpenTelemetry, LangGraph, CrewAI и AutoGen, разметка мультиагентных команд на кликабельном графе взаимодействий, схемы для мультимодальных агентов (GUI, голос, видео), а также арена моделей, проверки в CI и курирование.

Most agent evaluation stops at a score. Potato 2.6's trajectory_edit schema lets annotators rewrite a wrong step instead of rating it, and exports each correction as supervised fine-tuning targets and DPO preference pairs.
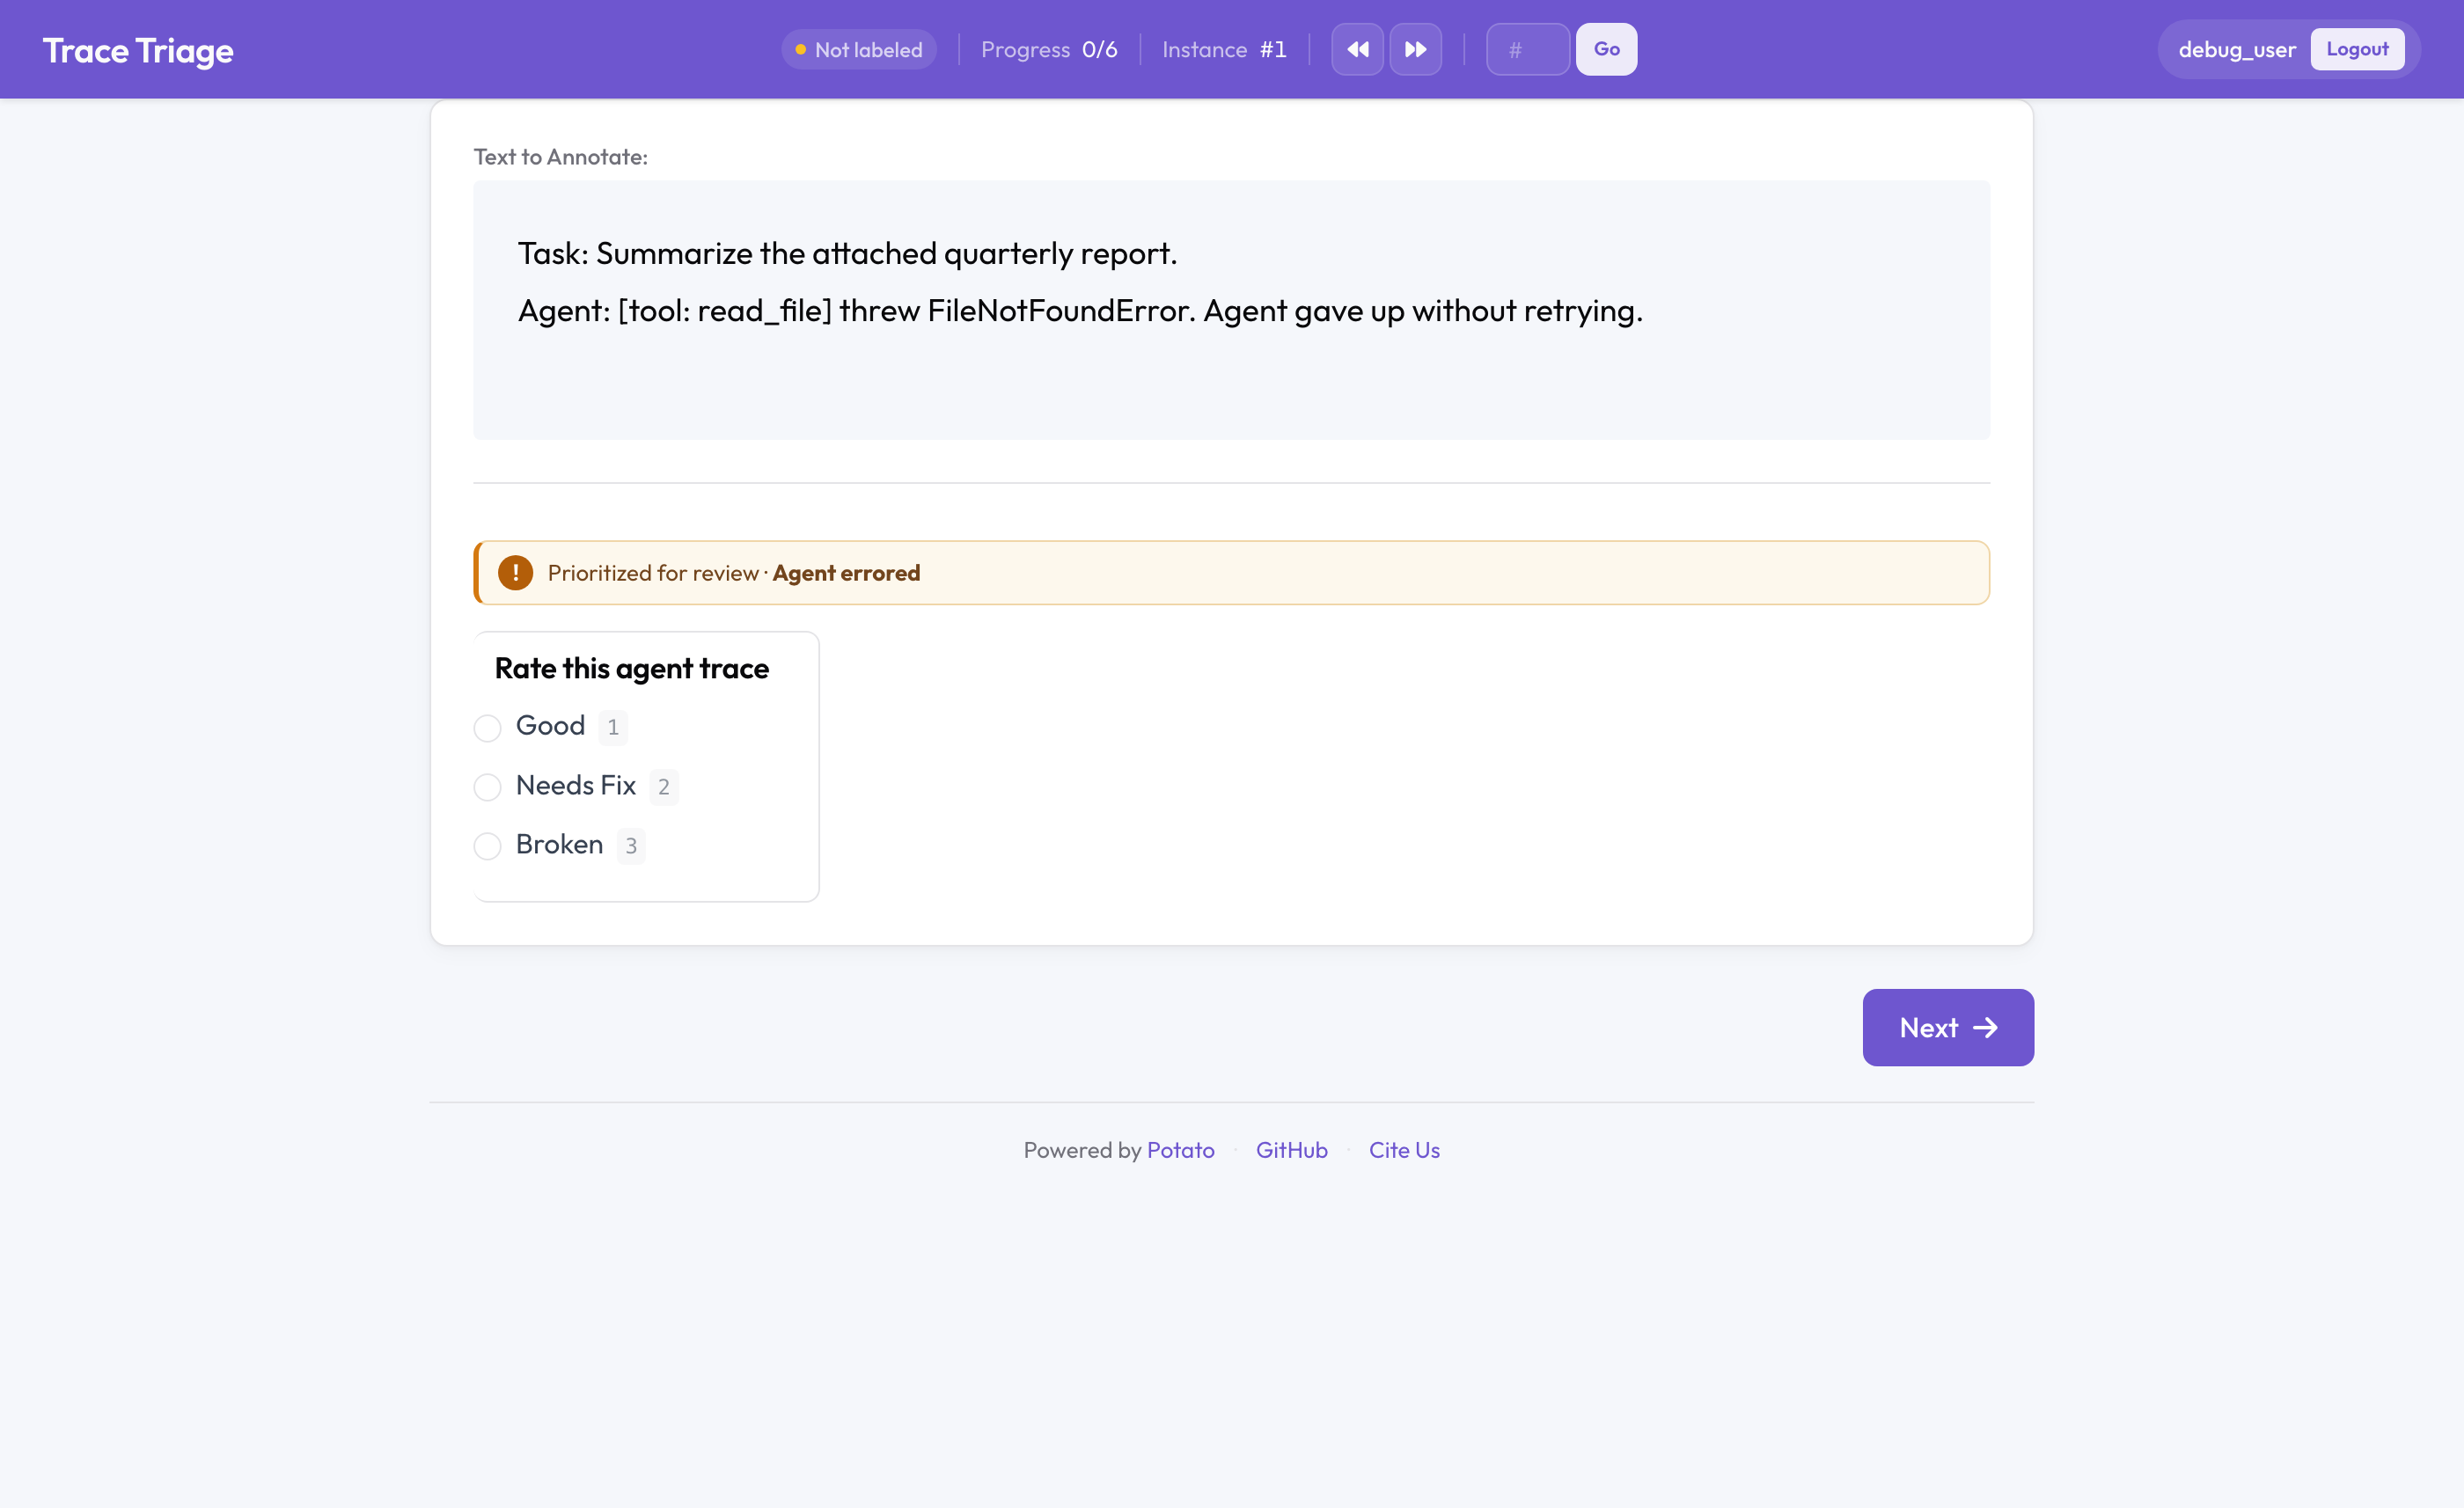
Annotating an agent's multi-step trace is harder than labeling a tweet. A guide to designing the taxonomy, measuring step-level agreement, and adjudicating disagreement, with a Potato config.


How to write an annotation codebook an LLM can actually follow, validate its labels against human coders, and keep a person in the loop, with a worked Potato config.
Catch model hallucinations and factual errors by highlighting the exact words and labeling what's wrong, MQM-style, with span annotation in Potato.


Tutorial for setting up live coding agent observation with Ollama, Anthropic API, or Claude Agent SDK. Includes pause, rollback, branching, and trajectory export.
Set up pairwise agent comparison in Potato across its three modes — binary preference, a preference scale, and per-dimension judgment with required justification.


Potato 2.4.0 ships web agent trace review, real-time live agent evaluation, an LLM chat sidebar, HuggingFace Hub export, webhooks, SSO/OAuth, and five active learning strategies.
Potato 2.3.0 adds Solo Mode for human-LLM labeling, agent trace annotation, Best-Worst Scaling, SSO and OAuth logins, Parquet export, and 15 demo projects.


Potato 2.1.0 brings the instance display system, visual AI support for image and video annotation, span linking, multi-field spans, and layout customization.
Configure YOLO, Ollama, OpenAI, and Claude vision endpoints in Potato so a model proposes boxes and labels that annotators accept or reject.


Настройка инструментов рисования полигонов в Potato для сегментации изображений: советы по сложным формам, перекрывающимся областям, многоклассовым полигонам и экспорту в COCO.
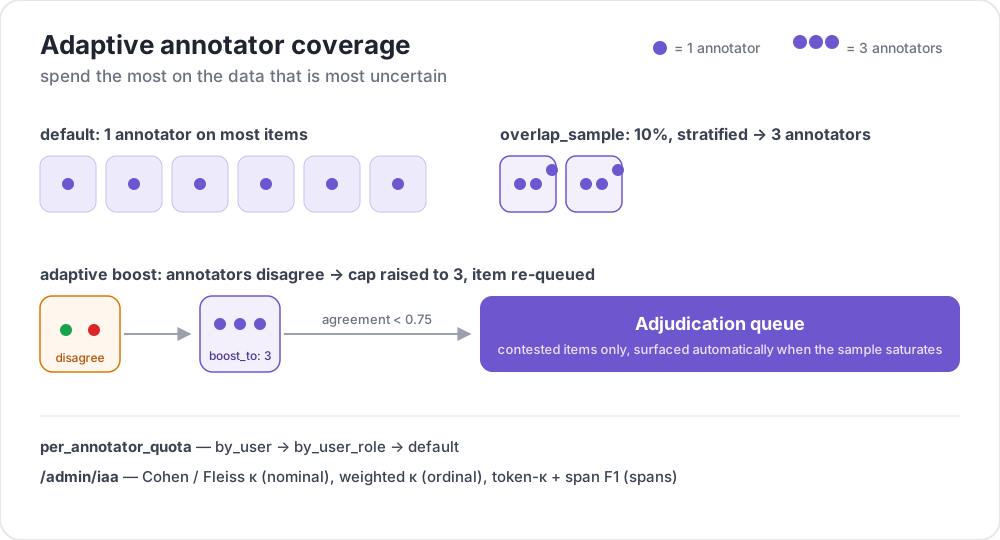
How Potato reorders the annotation queue by classifier uncertainty, with config for the sampling settings, the cold start, and keeping enough random items in the mix.


Configure keyword highlighting in Potato with a fixed keyword file or an LLM keyword assistant, covering per-label colors, randomized distractors, and response caching.
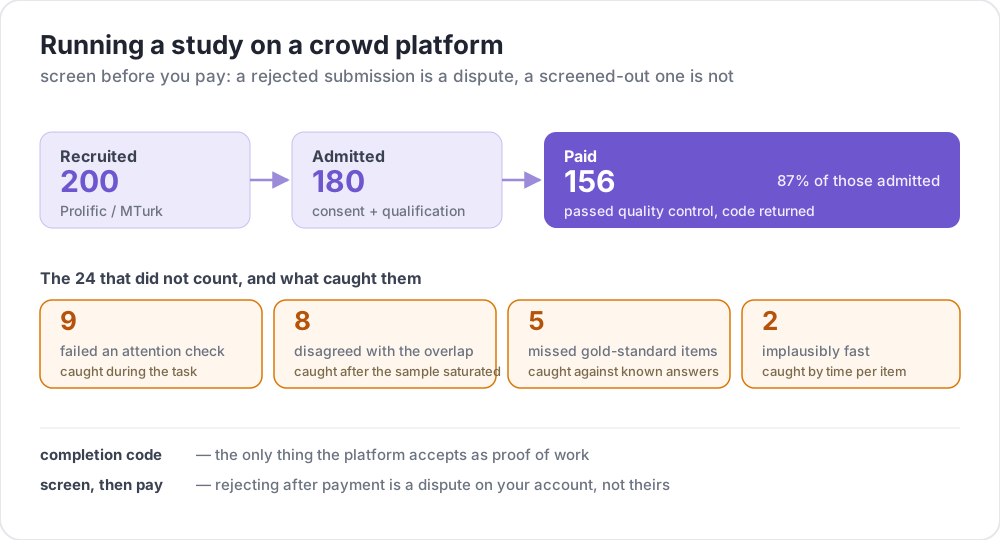
Запуск задач разметки Potato на Amazon Mechanical Turk: настройка HIT, квалификационные тесты, приём и отклонение работ, бонусные выплаты и наблюдение за качеством.


Build a speaker identification task in Potato with interactive audio waveforms, timestamp markers, speaker label assignment, and inter-annotator agreement measurement.
Set up video annotation in Potato with frame-by-frame navigation, timestamp markers, temporal event labeling, and per-segment classification using radio or span schemas.


Set up image classification in Potato by displaying images with instance_display and collecting labels with radio and multiselect schemes, including quality checks.
Wire OpenAI, Anthropic, Gemini, or a local model into Potato so annotators get hints, keyword highlights, and label rationales while keeping the final call.


Step-by-step guide to building a named entity recognition task in Potato, span annotation config, label colors, overlapping spans, keyboard shortcuts, and CoNLL export.
How Potato reads and writes JSON and JSONL: structuring instances for text, image, audio, video, and multimodal annotation, with a working config example for each.