Judging the Judge: Human and Model Reasoning, Side by Side
An LLM judge is only as trustworthy as the human labels it was checked against. Give those labels intervals, and compare human and model reasoning per item.
An LLM judge validated against human labels is only as trustworthy as those labels, so give each human label a confidence interval and report the judge's agreement separately for confident and ambiguous items. Comparing a person's chain of thought with the model's on the same item then shows whether the judge reached a label for the right reason.
An LLM judge is a common way to evaluate model output at scale, and anyone who uses one has to ask whether the judge can be trusted. The usual answer is to check it against human labels. "The judge agrees with humans" is a weak claim if the humans disagreed with each other and nobody wrote down by how much. Potato 2.7 is organized around the idea that an annotation tool should measure how a judgment was made as well as record it, for both kinds of judge.
Validating an LLM judge against majority votes
The standard workflow is reasonable. You have a task too big to label by hand, so you prompt a model to score it. Before trusting the scores, you take a sample, have humans label it, and measure agreement between the judge and the humans. If Cohen's κ is high enough, you ship.
The weakness is in the last step, because that κ compares your judge against a human label, usually a majority vote over two or three annotators. A majority vote is a point estimate with no error bar. It says "sarcastic" with exactly the same confidence whether all three annotators agreed instantly or two overruled a third after a long argument.
When you report that your judge agrees with humans at κ = 0.71, you are reporting agreement with a number whose own uncertainty you never measured. If the human labels on the hard items are close to coin flips, then κ on those items is mostly measuring noise, and no amount of prompt engineering will move it.
We wrote about the mechanics of judge calibration and judge–human alignment before. Potato 2.7 adds the other half, which is making the human side of that comparison carry its own uncertainty.
Error bars on human labels
The psychometrics engine fits an item response theory model to your human annotations and reports every label as a posterior with an interval (sarcastic, p = 0.94 [0.88 – 0.97]). The model weighs who voted rather than only how many. Truth Serum adds peer-prediction scoring, which flags the items where the crowd is probably wrong even though it was confident.
The judge comparison then changes shape. Instead of
the judge agrees with the majority label on 71% of items
you can say
the judge agrees with the human posterior on 94% of items where the human label is confident (p > 0.9), and 52% of items where it is not. Those low-confidence items are 18% of the set.
The second statement is actionable where the first is not. It tells you your judge is fine on the easy cases and unreliable on the hard ones, and how much of your data is hard. It also implies that on the genuinely ambiguous items there may be no ground truth for the judge to agree with, and that chasing a higher κ there is chasing noise. The judge–human alignment dashboard is built for that comparison, which is why the human-process and agent-evaluation features are the same release rather than two.
Two chains of thought on the same item
The other half of the comparison is the reasoning itself. Think-Aloud Mode records how a person reasons to a label. The annotator talks while they work, speech-to-text runs locally, and the transcript is stored verbatim and un-summarized, because paraphrasing a think-aloud protocol destroys the thing you were collecting.
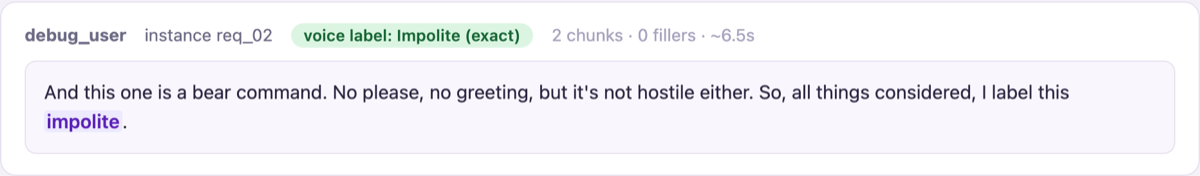 Human chain of thought, captured verbatim
Process-reward annotation records how a model reasons. The model's chain of thought is segmented into steps, and each step gets a good/bad/neutral reward signal, which is the training signal for a process reward model. The scheme looks like this:
annotation_schemes:
  - annotation_type: process_reward
    name: cot_review
    description: "Rate each step of the model's reasoning."
    steps_key: reasoning_steps
Uses of paired human and model reasoning
With both chains of thought for the same item side by side, the obvious use is finding where the model reasons differently from the person. Final-answer scoring cannot see the difference between a model that got the right answer for the right reason and one that got the right answer for the wrong reason. On a sarcasm task, a human might say "the 'thanks so much' is doing the work here. Nobody thanks you that hard for a two-day delay." A model might land on the same label because the text contains an exclamation mark. Both are marked correct, and only one of them will generalize. The reasoning shows that difference and the labels do not, which is why capturing both is worth the trouble.
The second use is training data. Steps where the human's reasoning and the model's diverge are the ones most worth a reviewer's time in a process-reward dataset. At each one, either the model's process is wrong in a way its output does not reveal or the human's is, and the reviewer's judgment on which becomes the step's reward label.
One limitation. Potato gives you both capture surfaces but does not compute an automated similarity metric between a human's chain of thought and a model's, and we have deliberately not shipped one. What "these two reasoning traces agree" means is an open research question, and a number we invented would be worse than no number, because it would look authoritative and mean very little. You get the paired traces, and the metric is yours to define.
Five steps for a defensible judge evaluation
None of these steps makes an LLM judge trustworthy by itself. They make the claim of trustworthiness checkable, as a statement with an interval on it, against human labels that also have intervals, on items whose difficulty you can describe. That bar is lower than "our judge is aligned with human values," and more useful. Every step is YAML, self-hosted, and free, and steps 1 through 3 need no LLM at all. In 2.7 the pipeline looks roughly like this:
- Label a sample with humans, with psychometrics on. Every label gets a posterior and an interval, and ambiguous items are identified as ambiguous rather than silently mislabeled.
- Run Truth Serum to catch the items where a confident crowd is probably wrong.
- Fix the guideline where the codebook-bug detector flags negative discrimination, ideally in a norming room where you can watch agreement move as you converge.
- Calibrate the judge against those labels, and report alignment conditioned on human confidence rather than as a single number.
- Check the reasoning as well as the verdict on the items where the judge and the humans disagree.
Further reading
- Judge–human alignment and judge calibration
- Labels with error bars, the IRT layer under all of this
- Quality control without gold labels
- Process reward models
- Think-Aloud Mode
- Potato 2.7, the full release