Instrumenting the Calibration Meeting
Multiplayer Rooms measure a norming session with blind votes and a live agreement meter. Think-Aloud Mode records spoken reasoning locally, with no LLM.
Potato 2.7 instruments the calibration meeting and the reasoning behind each label, two parts of annotation work that leave no record when they happen on a video call or in a free-text box. Multiplayer Rooms run the meeting as a live norming room with a real-time agreement meter, and Think-Aloud Mode records spoken reasoning with speech-to-text that runs locally, with no LLM in either.
Norming sessions in Multiplayer Rooms
A norming session is the meeting where annotators label the same handful of items, get on a call over screen-share, argue about the disagreements, and converge on what the guideline actually means. Run that way, the session happens outside the annotation tool and leaves no trace. The votes people held before the discussion are gone, and so is the record of who changed their mind and whether they were persuaded or deferred because a senior colleague spoke first. Nobody can say whether the meeting improved agreement at all, because nobody measured it. Multiplayer Rooms move that session into the tool.
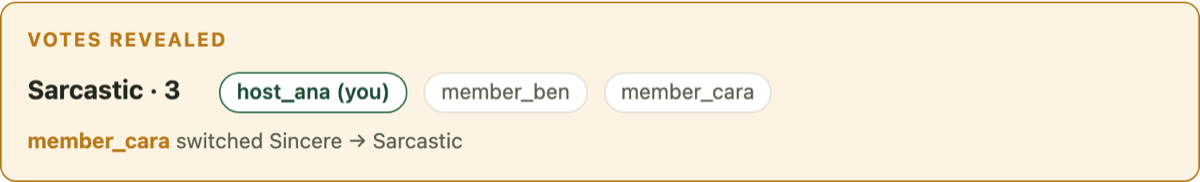 A norming room mid-session
Turn rooms on in the config:
rooms:
  enabled: true
  who_can_create: any
  persist_votes: true
  schema: sarcasm
who_can_create: any lets any logged-in user open a room (set it to admin to restrict rooms to admins), and persist_votes: true writes each member's final vote on a revealed item into their own annotations when the host advances or closes the room, so room work reaches the normal exports. Both settings are Potato's defaults.
Open /rooms and create a room, and it gets a six-letter code you can read aloud on the call. Every room follows the same four steps:
- Everyone votes blind. Members can see who has voted, never what. The server enforces the rule, so first impressions are genuinely independent.
- The host reveals. At that moment the blind votes become immutable.
- The group discusses, in a side chat or on your call.
- Anyone may change their vote. Potato logs every post-reveal change with what the member switched from, what they switched to, and what the majority was at that moment.
A vote changed after the reveal is a change made in the presence of a known majority, which makes it a different event from a blind vote. Logging it gives you a per-member conformity record, which is how you notice that one annotator flips to the majority every single time. You want to know that before you treat their agreement as independent evidence.
Live agreement meter and norming lift
Potato computes Krippendorff's α live over the revealed items twice, once on the blind votes and once on the current votes. The gap between the two is the session's norming lift, and it stays on screen while the session is happening.
If an hour of discussion moved α from 0.61 to 0.78, the hour bought something. If it moved α from 0.61 to 0.62, the disagreement is about the guideline rather than about interpretation, and more talking will not fix it. In that case, rewrite the guideline.
Room variants and the event log
Two variants extend the basic room. Huddles seed a room from exactly the items your team currently disagrees on, computed live from annotation state, which makes a huddle a synchronous version of adjudication. Shadow rooms let trainees watch a senior annotator work in real time, including which span of text they are highlighting, which is the closest thing to sitting next to someone while they annotate.
Potato event-sources each room to a JSONL log, so a live room survives a server restart and the log doubles as the session's audit trail. Clients poll with a cursor instead of holding WebSocket connections, so rooms work under any WSGI deployment.
Spoken rationales in Think-Aloud Mode
The second gap is rationales. Most tools offer a free-text box, and most annotators type "obvious" into it, or nothing. Writing out your reasoning is slower than having it, and if the task is 400 items long, the rationale box is the first thing to go.
The think-aloud protocol is an established method in psychology, usability testing, and decision-making research, in which participants say what they are thinking while they do a task and researchers transcribe the recordings for analysis. The annotation tools we know of do not record it, and narrating into a recorder for later transcription by hand is hard to keep up over a 400-item task. Think-Aloud Mode removes that friction by changing the modality, so annotators talk while they work instead of typing.
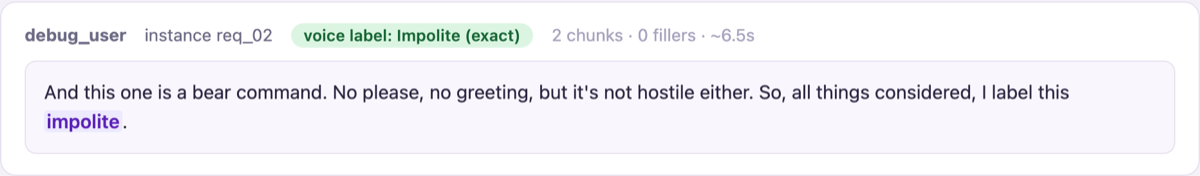 Think-Aloud, with a detected label
Turn Think-Aloud Mode on in the config:
thinkaloud:
  enabled: true
  schema: politeness
  model: tiny.en
Speech-to-text runs locally through faster-whisper, which is CPU real-time on the 39 MB tiny.en model. The audio never leaves the machine, and there is no cloud API to call or per-token bill to pay. For a lot of sensitive data, local transcription decides whether legal review approves the feature.
Verbatim transcripts and spoken labels
Potato stores the transcript exactly as spoken and deliberately does not summarize it, because paraphrasing a think-aloud protocol contaminates the artifact. The hesitations, the self-corrections, and the "well, it could be sarcastic, but..." are the data, and a tidy summary of them is a different and much less useful object.
Annotators can also commit a label by voice, using set phrasings that a rule-based parser detects:
- "I label this Polite"
- "My answer is impolite"
- "Final answer: neutral"
Only those phrasings commit a label. The parser ignores everything said while thinking, which is why a rule-based parser is sufficient, and no LLM runs anywhere in the pipeline, so no model decides what you meant. If an annotator says a new commitment phrase later, the last commitment wins.
Potato also computes deterministic hesitation signals (silent-chunk counts and filler-word counts) with arithmetic rather than a model. Long pauses on an item are a decent proxy for difficulty, and they cost nothing to collect.
Human and model chains of thought
Think-Aloud Mode is a human chain-of-thought recorder. It captures how a person actually reasons their way to a label as the reasoning happens, false starts included, instead of a cleaned-up justification written afterwards. Potato's process-reward annotation does the same job for a model. It segments a model's chain of thought and scores it step by step.
For the same item you then have two chains of thought, one human and one model, and you can put them side by side to see where the reasoning diverges. The pairing is the raw material for better process-reward data, because final-answer scoring cannot see the failure in which the model got the right answer for the wrong reason.
Potato gives you both capture surfaces and does not compute a diff between them. The comparison is a research question rather than a feature, and we would rather hand you the artifact than a metric we made up.
Further reading
- Multiplayer Rooms and Think-Aloud Mode, for the full configuration
- Inter-annotator agreement, on what α measures
- Adjudication and disagreement
- Labels with error bars, where psychometrics flags the codebook bugs that a room can fix
- Process reward models, on the model-side chain of thought