如何收集過程獎勵資料,訓練更好的編碼智慧體
用 Potato 收集逐步獎勵訊號、訓練 PRM 的分步指南,涵蓋首錯模式、逐步標註,以及匯出到訓練流水線。
什麼是過程獎勵模型
 標註過程獎勵的兩種方式
結果獎勵模型(ORM)只看編碼智慧體軌跡的結尾:程式碼編譯過了嗎,測試跑通了嗎,問題解決了嗎。過程獎勵模型(PRM)則給每一箇中間步驟打分。每一步都有獎勵訊號,訓練方法就能定位智慧體是從哪裡開始走錯的,這往往讓學習更省樣本,也有助於泛化。
近期的工作正朝這個方向推進。AgentPRM 為智慧體任務重新定義了過程獎勵:每個動作按它把任務推進到離目標多近來打分,而不是按對錯,論文報告的算力效率比其對比的基線高出 8 倍以上。ToolRM 發現,在自然語言輸出上訓練的獎勵模型判斷工具呼叫的能力很差,於是構建了面向工具的獎勵模型,以及用來評測它們的 FC-RewardBench。作為對照,DeepSWE 只用一個稀疏的結果獎勵(測試是否通過)來訓練編碼智慧體,在 SWE-bench Verified 上達到 Pass@1 42.2%,配合測試時擴充套件達到 59%。過程監督想要改進的,正是這種只看結果的設定。
這些方法共同需要的是高品質的步驟級人工標註,而這通常就是瓶頸。Potato 的過程獎勵方案就是為了讓這類資料收集得更快。底層方案見軌跡評估文件,trace 輸入格式的細節見智慧體 trace 文件。
兩種標註模式
Potato 提供兩種 PRM 標註模式,在速度和粒度之間做取捨。按你的資料預算和目標挑一種。
首錯模式
在首錯模式下,標註者從上到下讀完軌跡,點選智慧體第一次出錯的那一步。Potato 隨後把這一步之前的所有步驟標為正確,把這一步及之後的所有步驟標為錯誤。
這種方式快,因為標註者只需要找一個決策點。當錯誤會連鎖傳播時它很好用,也就是說智慧體一旦走偏就很少能自己回來,而這在實際中是常態。
annotation_schemes:
  - annotation_type: process_reward
    name: prm_first_error
    mode: "first_error"
    description: >
      Review the agent's steps from top to bottom. Click on the
      first step where the agent makes a mistake. All steps before
      your selection will be marked correct; all steps after
      (including the selected step) will be marked incorrect.
首錯標註的流程是這樣的:
- 標註者開啟一條 trace,看到所有步驟由 CodingTraceDisplay 元件渲染出來。
- 他們按順序讀完這些步驟,檢視 diff、終端輸出和推理過程。
- 找到第一個錯誤步驟時,點選它旁邊的錯誤標記。
- 第 0 步到第 N-1 步變綠(正確),第 N 步到結尾變紅(錯誤)。
- 標註者檢查自動打上的標籤,點選 “Submit” 確認。
如果整條 trace 都正確(智慧體完美解決了任務),標註者點 “All Correct”。如果第一步就已經錯了,就點第 0 步或者用 “All Incorrect”。
下面是 PRM 標註介面的實際樣子:
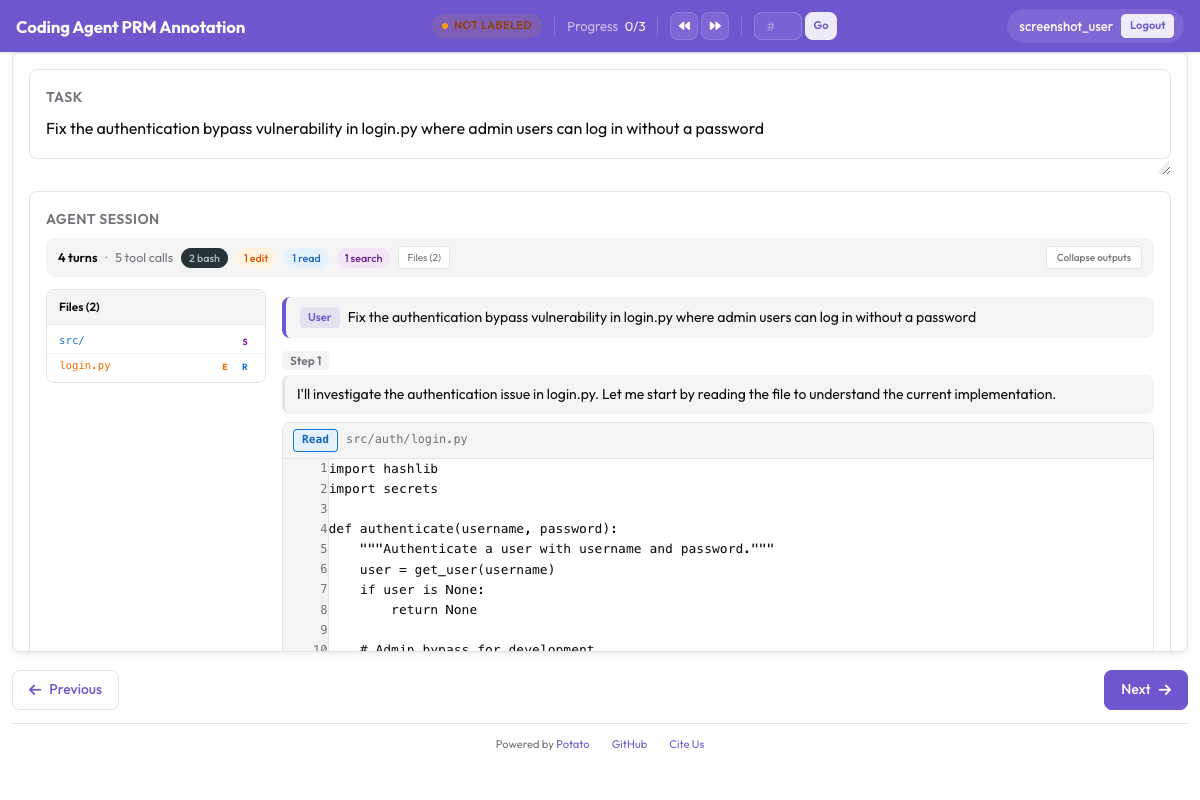 在首錯模式下,點選第一個錯誤步驟,後續步驟會自動標記
逐步模式
在逐步模式下,每一步都有自己的標籤。這樣得到的資料更豐富,因為它能記錄智慧體從錯誤中部分恢復、繞了一段無害但沒必要的路,或者某一步本身沒問題但放在上下文裡是錯的這類情況。
annotation_schemes:
  - annotation_type: process_reward
    name: prm_per_step
    mode: "per_step"
搭建一個 PRM 標註項目
第 1 步:準備 trace 資料
輸入資料應該是一個 JSONL 檔案,每一行是一個包含智慧體軌跡的 JSON 物件。關鍵欄位是 id、issue_description 和 structured_turns:
{
  "id": "trace_001",
  "issue_description": "Fix the TypeError in parse_config() when config file is empty",
  "repo": "myorg/myproject",
  "base_commit": "a1b2c3d",
  "structured_turns": [
    {
      "step_idx": 0,
      "type": "thinking",
      "content": "I need to understand what parse_config does and where the TypeError occurs. Let me read the file first."
    },
    {
      "step_idx": 1,
      "type": "file_read",
      "path": "src/config.py",
      "content": "def parse_config(path):\n    with open(path) as f:\n        data = json.load(f)\n    return data['settings']",
      "start_line": 1,
      "end_line": 4
    },
    {
      "step_idx": 2,
      "type": "thinking",
      "content": "The bug is on line 4. When the file is empty, json.load returns None, and None['settings'] raises TypeError. I should add a check."
    },
    {
      "step_idx": 3,
      "type": "file_edit",
      "path": "src/config.py",
      "diff": "--- a/src/config.py\n+++ b/src/config.py\n@@ -1,4 +1,6 @@\n def parse_config(path):\n     with open(path) as f:\n         data = json.load(f)\n+    if data is None:\n+        return {}\n     return data['settings']"
    },
    {
      "step_idx": 4,
      "type": "bash_command",
      "command": "python -m pytest tests/test_config.py -v",
      "output": "tests/test_config.py::test_parse_config_empty PASSED\ntests/test_config.py::test_parse_config_valid PASSED\n\n2 passed in 0.12s",
      "exit_code": 0
    }
  ]
}
如果你要從已有的智慧體格式轉換過來,用 trace 轉換工具:
# Convert Claude Code traces
potato convert-traces \
  --format claude_code \
  --input ./raw_traces/ \
  --output ./data/traces.jsonl

# Convert SWE-Agent trajectories
potato convert-traces \
  --format swe_agent \
  --input ./swe_agent_output/ \
  --output ./data/traces.jsonl
Potato 渲染編碼智慧體 trace 時會正確高亮 diff:
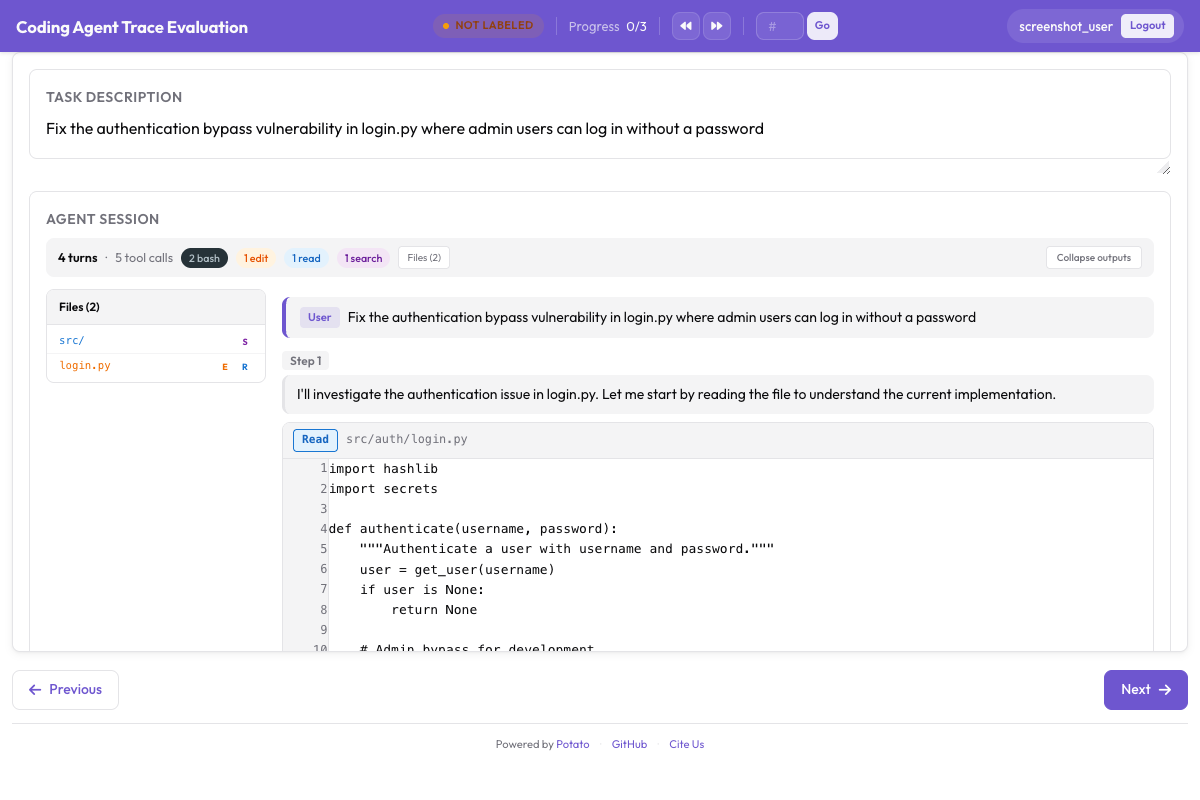 程式碼 diff、終端輸出和檔案讀取都帶語法高亮渲染
第 2 步:寫配置檔案
下面是一份用首錯模式做 PRM 標註的完整項目配置:
# config.yaml
project_name: "PRM Data Collection - SWE-bench Traces"
port: 8000

data:
  source: "local"
  input_path: "./data/traces.jsonl"
  data_format: "coding_trace"

coding_agent:
  display:
    diff_style: "unified"
    context_lines: 3
    syntax_highlighting: true
    terminal_theme: "dark"
    file_tree:
      enabled: true
      position: "left"
    collapsible:
      auto_collapse_thinking: true
      auto_collapse_long_output: true
      long_output_threshold: 50

annotation_schemes:
  - annotation_type: process_reward
    name: step_reward
    mode: "first_error"
    description: >
      Review the agent's trajectory step by step. Click the first
      step where the agent makes an error. If the entire trajectory
      is correct, click "All Correct."

  - annotation_type: radio
    name: outcome
    labels:
      - value: "resolved"
        text: "Fully Resolved"
      - value: "partial"
        text: "Partially Resolved"
      - value: "not_resolved"
        text: "Not Resolved"

  - annotation_type: text
    name: error_description
    description: "If incorrect, briefly describe the error"
    placeholder: "e.g., Agent edited the wrong file..."

output:
  path: "./output/"
  format: "jsonl"

quality_control:
  inter_annotator_agreement: true
  overlap_percentage: 15
  minimum_time_per_instance: 20

annotators:
  - username: "reviewer1"
  - username: "reviewer2"
  - username: "reviewer3"
第 3 步:啟動標註服務
# Start the annotation server
potato start config.yaml -p 8000

# Or run in the background
nohup potato start config.yaml -p 8000 > potato.log 2>&1 &
開啟 http://localhost:8000,用配置裡的任一標註者賬號登入,就可以開始審閱 trace 了。
第 4 步:跟蹤進度
標註進行期間,隨時檢視進度和一致性:
# Check annotation progress
potato status config.yaml

# View inter-annotator agreement
potato agreement config.yaml --metric krippendorff_alpha
匯出到訓練格式
標註完成後,按訓練流水線需要的格式匯出資料。
用於獎勵模型訓練的 PRM 格式
PRM 匯出格式為每條 trace 生成一個帶步驟級標籤的 JSON 物件:
potato export \
  --format prm \
  --project ./output/ \
  --output ./training_data/prm_labels.jsonl
輸出長這樣:
{
  "trace_id": "trace_001",
  "issue_description": "Fix the TypeError in parse_config() when config file is empty",
  "total_steps": 5,
  "first_error_step": null,
  "all_correct": true,
  "steps": [
    {"step_idx": 0, "type": "thinking", "label": "correct", "reward": 1.0},
    {"step_idx": 1, "type": "file_read", "label": "correct", "reward": 1.0},
    {"step_idx": 2, "type": "thinking", "label": "correct", "reward": 1.0},
    {"step_idx": 3, "type": "file_edit", "label": "correct", "reward": 1.0},
    {"step_idx": 4, "type": "bash_command", "label": "correct", "reward": 1.0}
  ]
}
DPO/RLHF 偏好對
當同一個問題有多條 trace 時(比如來自不同智慧體或不同次執行),Potato 可以基於 PRM 標籤生成偏好對:
potato export \
  --format preference_pairs \
  --project ./output/ \
  --output ./training_data/preferences.jsonl \
  --pair_by "issue_id"
偏好對匯出會比較嘗試同一任務的多條 trace,按步驟級標籤選出更好的那一條:
{
  "prompt": "Fix the TypeError in parse_config() when config file is empty",
  "chosen_trace_id": "trace_001",
  "rejected_trace_id": "trace_002",
  "chosen_first_error": null,
  "rejected_first_error": 3,
  "chosen_steps": 5,
  "rejected_steps": 7,
  "margin": 0.8
}
SWE-bench 相容結果
匯出成 SWE-bench 格式用於基準測試:
potato export \
  --format swe_bench \
  --project ./output/ \
  --output ./training_data/swe_bench_results.json
分析示例
收集完標註之後,可以用下面這些 Python 片段分析資料、找出規律。
按步驟類型統計步驟級準確率
import json
from collections import defaultdict

# Load PRM annotations
with open("training_data/prm_labels.jsonl") as f:
    traces = [json.loads(line) for line in f]

# Compute accuracy by step type
type_stats = defaultdict(lambda: {"correct": 0, "total": 0})

for trace in traces:
    for step in trace["steps"]:
        step_type = step["type"]
        type_stats[step_type]["total"] += 1
        if step["label"] == "correct":
            type_stats[step_type]["correct"] += 1

print("Step-Level Accuracy by Type:")
print("-" * 45)
for step_type, stats in sorted(type_stats.items()):
    acc = stats["correct"] / stats["total"] * 100
    print(f"  {step_type:<20} {acc:5.1f}%  ({stats['correct']}/{stats['total']})")
找出常見的失敗點
import json
from collections import Counter

with open("training_data/prm_labels.jsonl") as f:
    traces = [json.loads(line) for line in f]

# Analyze where errors first occur
error_positions = []
error_types_at_first_error = Counter()

for trace in traces:
    if trace["first_error_step"] is not None:
        pos = trace["first_error_step"]
        total = trace["total_steps"]
        # Normalize position to 0-1 range
        error_positions.append(pos / total)
        # Track what type of step caused the first error
        error_step = trace["steps"][pos]
        error_types_at_first_error[error_step["type"]] += 1

if error_positions:
    avg_pos = sum(error_positions) / len(error_positions)
    print(f"Average first-error position: {avg_pos:.2f} (0=start, 1=end)")
    print(f"Traces with errors: {len(error_positions)}/{len(traces)}")
    print()
    print("Most common step types at first error:")
    for step_type, count in error_types_at_first_error.most_common(5):
        print(f"  {step_type}: {count}")
計算 PRM 標籤的標註者間一致性
import json
import numpy as np
from sklearn.metrics import cohen_kappa_score

def load_annotations(annotator_file):
    """Load annotations from a single annotator's output file."""
    with open(annotator_file) as f:
        data = {item["trace_id"]: item for item in
                (json.loads(line) for line in f)}
    return data

ann1 = load_annotations("output/reviewer1/annotations.jsonl")
ann2 = load_annotations("output/reviewer2/annotations.jsonl")

# Find overlapping traces
overlap_ids = set(ann1.keys()) & set(ann2.keys())
print(f"Overlapping traces: {len(overlap_ids)}")

# Compare first-error step labels
labels1 = []
labels2 = []
for trace_id in overlap_ids:
    fe1 = ann1[trace_id].get("first_error_step", -1)
    fe2 = ann2[trace_id].get("first_error_step", -1)
    # Bin into: all_correct, early_error (first half), late_error (second half)
    total = ann1[trace_id]["total_steps"]
    for fe, labels in [(fe1, labels1), (fe2, labels2)]:
        if fe is None or fe == -1:
            labels.append("all_correct")
        elif fe < total / 2:
            labels.append("early_error")
        else:
            labels.append("late_error")

kappa = cohen_kappa_score(labels1, labels2)
print(f"Cohen's kappa (binned first-error): {kappa:.3f}")
高效收集 PRM 資料的幾點建議
要快就用首錯模式。如果你訓練 PRM 是為了引導搜尋(MCTS、best-of-N 取樣),首錯模式給的訊號已經夠用,而標註速度是逐步模式的 2 到 3 倍。反正大多數智慧體的失敗都是連鎖式的:一步錯,後面一串都跟著錯。
需要細節時用逐步模式。如果你在意部分恢復、無害的繞路,或者你要訓練一個標籤多於兩類的步驟級獎勵模型,逐步模式多花的時間是值得的。
把 PRM 和成對比較結合。先用 PRM 單獨標註每條 trace,再對嘗試同一個問題的 trace 做一次成對比較。一輪標註同時拿到步驟級獎勵和偏好對。
先找有經驗的標註者。PRM 標註要讀程式碼、diff 和終端輸出。先從一小組有經驗的開發者開始,量一下一致性,用樣例校準過,再擴大規模。
設一個每條資料的最短時間。trace 會變得很複雜。30 秒的下限能防止標註者不看改動就一路點下去。這個值按你的平均 trace 長度調。
準備校準樣例。正式標註之前,讓所有人標同樣的 10 到 20 條 trace,然後一起過一遍分歧在哪。這對一致性影響很大。