編碼智慧體標註:評測 Claude Code、Aider 與 SWE-Agent 軌跡
Potato 把編碼智慧體軌跡渲染成差異檢視和終端塊,提供過程獎勵與程式碼審查兩種標註方案,以及 Claude Code、Aider、SWE-Agent 的軌跡轉換器。
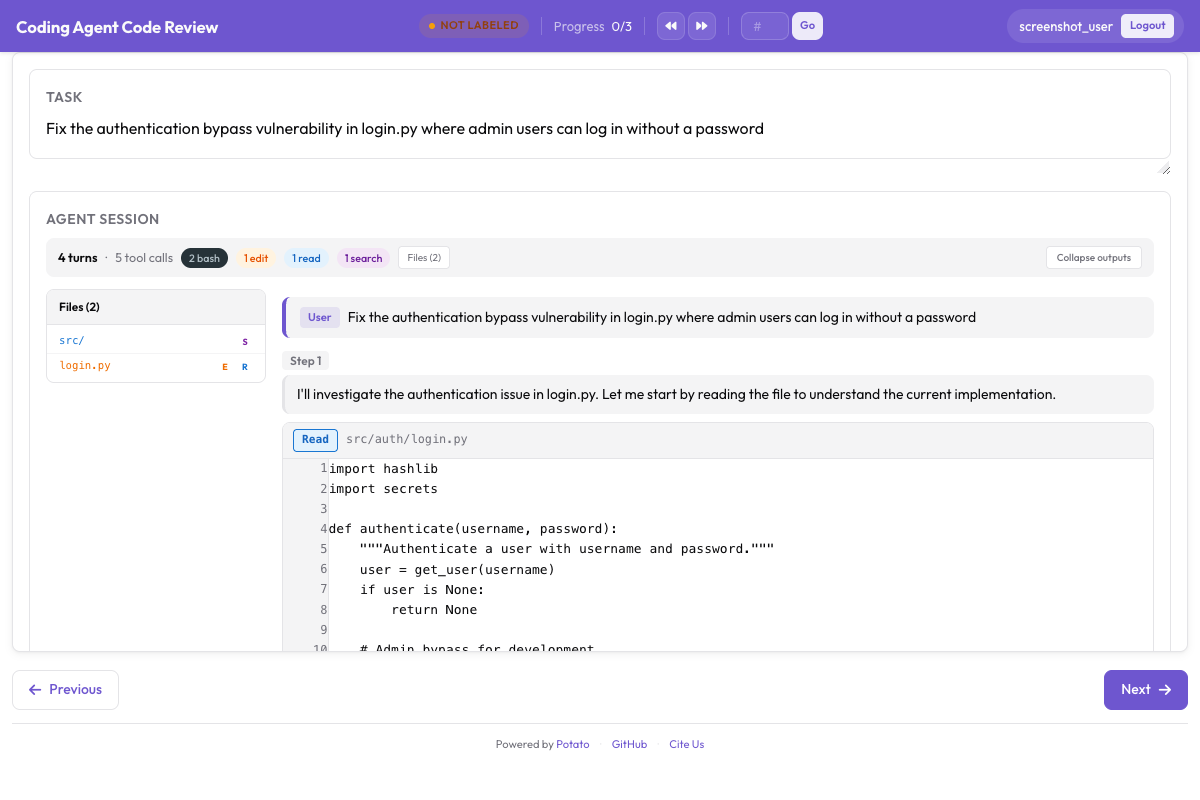
Potato 現在可以直接標註編碼智慧體的會話。一條軌跡會渲染成統一差異、深色終端塊、帶行號的檔案讀取內容,以及智慧體改動過的所有檔案構成的檔案樹;編碼智慧體格式有三個轉換器(claude_code、aider 和 swe_agent_trajectory),此外 Potato 原本就能讀取另外十二種軌跡格式;還有兩個專為這類資料設計的標註方案:process_reward 用於步驟級的對錯判斷,code_review 用於以 GitHub 的方式審查這些差異。
一次編碼智慧體的執行是一條很長的軌跡,由檔案讀取、編輯、終端命令和推理串成。純文本的標註介面會把這些全部壓平成一堵字元牆,所以做智慧體評測的團隊往往自己寫一套審查介面,最後得到別人用不了的資料集。完整參考見編碼智慧體標註文件和智慧體評測指南。
規劃研究前要先確認的兩件事
Claude Code 的會話記錄裡沒有模型的思考文本。檔案保留了 thinking 塊和它的簽名,但丟棄了內容;在 40 個本地會話中統計到 6,393 個這樣的塊,沒有一個帶文本。轉換後的軌跡會報出這個數量,讓缺失可見而不是悄悄發生。如果標註者需要看到推理過程才能判斷各個步驟,就用 claude -p --output-format stream-json 或者 Agent SDK 即時抓取,不要事後從磁碟讀回。
會話記錄裡還帶著絕對路徑、分支名、環境資訊,以及會話讀取過的任何原始碼。分享資料集之前先做脫敏,並且要取得會話所有者的同意。
軌跡顯示
編碼軌跡通過 coding_trace 顯示類型渲染,在 instance_display 中與標註者該看到的其他內容一起宣告。Potato 把"顯示什麼"和"問什麼"分開,所以同一個軌跡顯示可以配合任何標註方案使用:
instance_display:
  layout:
    direction: vertical
    gap: 16px
  fields:
    - key: task_description
      type: text
      label: "Task"
    - key: structured_turns
      type: coding_trace
      label: "Agent Session"
      display_options:
        show_file_tree: true
        diff_view: unified
        collapse_long_outputs: true
        max_output_lines: 50
        terminal_theme: dark
        show_step_numbers: true
        show_reasoning: true
每個工具呼叫都按它實際做的事來渲染,這樣標註者看到的差異就是差異,而不是轉義過的文本:
| 工具 | 渲染方式 |
|---|---|
Read | 帶行號的程式碼塊 |
Edit、Replace | 紅綠雙色的統一差異 |
Write、Create | 新檔案程式碼塊,整段為綠色 |
Bash、Terminal、Shell | 帶 $ 提示符的深色終端塊 |
Grep、Glob、Search、Find | 搜尋結果程式碼塊 |
| 其他工具 | JSON 格式的輸入與輸出 |
 帶有統一差異、終端輸出和檔案樹側邊欄的編碼軌跡
collapse_long_outputs 配合 max_output_lines: 50,決定了一條軌跡讀不讀得下去。一次 pytest 執行就可能列印幾百行,而每一步都要滾過這些內容的標註者會乾脆不看步驟了。
資料格式
structured_turns 格式保留了顯示所需的工具呼叫結構。每一輪帶有角色、文本內容和一組工具呼叫:
{
  "id": "session_001",
  "task_description": "Fix the authentication bypass in login.py",
  "model": "claude-sonnet-4-20250514",
  "structured_turns": [
    {
      "role": "assistant",
      "content": "I'll investigate the auth issue.",
      "tool_calls": [
        {
          "tool": "Read",
          "input": {"file_path": "src/auth/login.py"},
          "output": "def login(user, password):\n    if user.role == 'admin':\n        return True",
          "output_type": "code",
          "language": "python"
        },
        {
          "tool": "Bash",
          "input": {"command": "pytest tests/test_auth.py -v"},
          "output": "4 passed",
          "output_type": "terminal"
        }
      ]
    }
  ]
}
output_type 可取 code、diff、terminal 或 generic;不填時 Potato 會根據工具和副檔名推斷。當某個工具的輸出和它的名字不相符時,就顯式寫出來。
轉換你手上已有的軌跡
轉換器讀入一種格式,寫出 Potato 載入的 JSONL。其中三種格式屬於編碼智慧體:
# Claude Code, or any Anthropic Messages API transcript
python -m potato.trace_converter -i traces.json -f claude_code -o data/traces.jsonl

# Aider chat history with SEARCH/REPLACE blocks
python -m potato.trace_converter -i chat.md -f aider -o data/traces.jsonl

# SWE-Agent trajectories
python -m potato.trace_converter -i trajectory.json -f swe_agent_trajectory -o data/traces.jsonl

# Mixed directory, format detected per file
python -m potato.trace_converter -i traces.json --auto-detect -o data/traces.jsonl
claude_code 轉換器既能讀 Claude Code 自己的會話記錄,也能讀原始的 Messages API 結構。Claude Code 會為每個會話在 ~/.claude/projects/<slugified-working-directory>/<session-id>.jsonl 下寫一個 JSONL 檔案,轉換器把一個會話變成一條軌跡,而不是一行一條:
python -m potato.trace_converter \
  -i ~/.claude/projects/-home-me-myrepo/3c853f0f-....jsonl \
  --auto-detect -o data/session.jsonl
它會沿著 parentUuid 鏈走,只保留最終存活的那條路徑,因此被回退掉的嘗試會被丟棄並計數,而不是當作真發生過來標註。側鏈訊息進入 sidechain_runs,不混在主輪次裡。斜槓命令會被丟棄,因為那是 CLI 在和自己說話。磁碟上的這套結構屬於 CLI 而不是公開 API,所以跨版本升級時要把這個讀取器當成盡力而為的實現。它會忽略自己不認識的記錄類型;當某個檔案解析不下去時,它會拋錯而不是交回一條空軌跡。
過程獎勵標註
過程獎勵模型逐步分配功過,而不是隻給最終結果打分,process_reward 收集的就是訓練它所需的標籤。兩種模式在速度和精細度之間做不同的取捨。
在預設的 first_error 模式下,標註者點選智慧體第一次出錯的那一步。它之前的每一步都標為正確,這一步及其之後的所有步驟都標為錯誤。一次點選就標完整條軌跡,所以需要產量的時候用這個模式。
annotation_schemes:
  - annotation_type: process_reward
    name: step_rewards
    description: "Click the first step where the agent makes a mistake."
    steps_key: structured_turns
    mode: first_error
在 per_step 模式下,每一步各自獨立評判。這會花掉更多標註時間,但能產出 first_error 給不了的訊號,因為級聯式標註假定錯誤不可挽回,而真實的智慧體是會自我糾正的。再開啟 allow_neutral,標籤就遵循 PRM800K 的 +1、0、-1 約定,真正無害的步驟記為中性,而不是被迫歸到某一極:
  - annotation_type: process_reward
    name: step_rewards
    description: "Label each step as correct, neutral, or incorrect."
    steps_key: structured_turns
    step_text_key: content
    mode: per_step
    allow_neutral: true
把這兩種方案中的任意一個加到上面的配置裡。開啟 allow_neutral 後,未標記的步驟保持為 null,因此匯出結果能區分"標註者判定為中性"和"標註者根本沒看到這一步"。allow_neutral 只對 per_step 生效,在 first_error 下會被強制關閉,因為那裡沒有中性判斷的位置。
程式碼審查標註
code_review 方案把拉取請求式的評審帶到智慧體的產出上。標註者點選差異中的某一行來附上帶分類的評論,給每個檔案打分,並給出結論:
  - annotation_type: code_review
    name: review
    description: "Review the agent's code changes."
    comment_categories: [bug, style, suggestion, security]
    verdict_options: [approve, request_changes, comment_only]
    file_rating_dimensions: [correctness, quality]
把這個方案加到上面的配置裡。檔案評分維度各按 1 到 5 打分。預設值對一般的審查工作是合適的,所以只有當你的分類體系本身就是研究重點時才去覆蓋它,比如在一次安全審查中,bug 和 security 需要成為兩個獨立的類別,並在指南中分別定義。
 行內差異評論、逐檔案評分和總體結論
程式碼審查教程完整走了一遍審查研究,包括評論類別如何影響標註者注意到什麼。在放大規模之前,先拿少量軌跡跑一遍這個研究,因為一份在配置裡看著很完整的類別清單,通常在頭二十次審查之後還會再多出一項。
一份完整的配置
這份配置渲染軌跡,收集任務級結論、首錯模式的過程獎勵和一次程式碼審查,每條軌跡分配三名標註者,以便測量一致性:
annotation_task_name: "Coding Agent Trace Evaluation"
task_description: "Judge whether the agent completed the task and review its changes."

data_files:
  - data/traces.jsonl

item_properties:
  id_key: id
  text_key: task_description

port: 8000
output_annotation_dir: annotation_output/coding-agent-eval/
export_annotation_format: jsonl

instance_display:
  layout:
    direction: vertical
    gap: 16px
  fields:
    - key: task_description
      type: text
      label: "Task"
    - key: structured_turns
      type: coding_trace
      label: "Agent Session"
      display_options:
        show_file_tree: true
        diff_view: unified
        collapse_long_outputs: true
        max_output_lines: 50
        terminal_theme: dark
        show_step_numbers: true

annotation_schemes:
  - annotation_type: radio
    name: task_success
    description: "Did the agent complete the task?"
    labels:
      - name: success
        tooltip: "Completed correctly with no issues"
      - name: partial
        tooltip: "Completed with minor issues"
      - name: failure
        tooltip: "Not completed, or completed incorrectly"
    sequential_key_binding: true

  - annotation_type: process_reward
    name: step_rewards
    description: "Click the first step where the agent makes a mistake."
    steps_key: structured_turns
    mode: first_error

  - annotation_type: code_review
    name: review
    description: "Review the agent's code changes."
    comment_categories: [bug, style, suggestion, security]
    verdict_options: [approve, request_changes, comment_only]
    file_rating_dimensions: [correctness, quality]

  - annotation_type: text
    name: notes
    description: "Anything else worth recording about this trace"
    placeholder: "Optional"

num_annotators_per_item: 3

user_config:
  allow_all_users: false
  users:
    - annotator1
    - annotator2
安裝 Potato、轉換你的軌跡,然後啟動服務:
pip install potato-annotation
python -m potato.trace_converter -i ./my_traces.json --auto-detect -o data/traces.jsonl
potato start config.yaml -p 8000
倉庫在 examples/agent-traces/coding-agent-evaluation/ 下附帶了這個項目的可執行版本,在你轉換自己的資料之前,這是看到顯示效果最快的辦法。啟動那份配置,像標註者那樣讀一條軌跡,幾分鐘之內你就能知道你打算標註的步驟粒度是不是顯示所呈現的粒度。
為訓練匯出
標註通過編碼評測匯出器輸出,每種輸出類型寫一個檔案:
python -m potato.export -c config.yaml -f coding_eval -o exports/ \
--option types=prm,preference,swebench,code_review| 類型 | 檔案 | 用途 |
|---|---|---|
prm | prm_training_data.jsonl | 訓練過程獎勵模型 |
preference | preference_pairs.jsonl | DPO 或 RLHF,來自成對標註 |
swebench | swebench_results.jsonl | 與 SWE-bench 相容的評測 |
code_review | code_reviews.jsonl | 結構化的審查資料 |
preference 類型需要有成對標註才能生成,所以只收集過程獎勵的研究會產出另外三種。在設計標註方案之前就決定這四種裡你要哪幾種,因為事後再補一次成對比較,意味著每條軌跡都要對著一個搭檔再標一遍。
看著智慧體幹活
錄製下來的軌跡只是故事的一半。live_coding_agent 會在標註頁面裡跑一個智慧體,標註者可以看著它工作、中途介入、回滾,並換一套指令重放,後端可以是 Ollama、Anthropic 或 Claude SDK,執行在一個沙箱化的工作目錄中。即時編碼智慧體文件介紹了各個後端和沙箱模式。
如果你的團隊在評測編碼智慧體,遇到了這套方案覆蓋不到的情況,歡迎到 GitHub 倉庫提 issue。新寫一個轉換器大致就是 potato/trace_converter/converters/ 下的一個檔案,所以 Potato 還讀不了的格式是一次貢獻的機會,而不是一堵牆。