感情分析タスクの作成
ラジオボタン、ツールチップ、キーボードショートカットを備えた感情分類タスクを一通り構築し、効率よくラベル付けできるようにします。
感情分析は最も一般的なNLPタスクの一つで、Potatoでそのためのきれいなラベルを集めるのは難しくありません。本チュートリアルでは、実際にアノテーターに渡せる感情アノテーションインターフェースを構築します。ラベル付けを速くするキーボードショートカットと品質チェックも含めます。
プロジェクト概要
ソーシャルメディアの投稿にアノテーションを行います。インターフェースには次のものが含まれます。
- 3値の感情分類(Positive、Negative、Neutral)
- 各アノテーションの確信度評価
- 任意のテキストによる説明
- 作業を速くするキーボードショートカット
- 品質管理の仕組み
完全な設定
config.yamlの全体は次のとおりです。
annotation_task_name: "Social Media Sentiment Analysis"

# Data configuration
data_files:
  - "data/tweets.json"

item_properties:
  id_key: id
  text_key: text

# Annotation interface
annotation_schemes:
  # Primary sentiment label
  - annotation_type: radio
    name: sentiment
    description: "What is the overall sentiment of this post?"
    labels:
      - name: Positive
        tooltip: "Expresses happiness, satisfaction, or approval"
        key_value: "1"
      - name: Negative
        tooltip: "Expresses sadness, frustration, or disapproval"
        key_value: "2"
      - name: Neutral
        tooltip: "Factual, objective, or lacks emotional content"
        key_value: "3"
    label_requirement:
      required: true

  # Confidence rating
  - annotation_type: likert
    name: confidence
    description: "How confident are you in your sentiment label?"
    size: 5
    min_label: "Not confident"
    max_label: "Very confident"
    label_requirement:
      required: true

  # Optional explanation
  - annotation_type: text
    name: explanation
    description: "Why did you choose this label? (Optional)"
    rows: 4
    label_requirement:
      required: false
    placeholder: "Explain your reasoning..."

# Guidelines
annotation_instructions: |
  ## Sentiment Annotation Guidelines

  ### Your Task
  Classify the sentiment expressed in each social media post.

  ### Labels

  **Positive**: The author expresses positive emotions or opinions
  - Happiness, excitement, gratitude
  - Praise, recommendations, approval
  - Examples: "Love this!", "Best day ever!", "Highly recommend"

  **Negative**: The author expresses negative emotions or opinions
  - Anger, frustration, sadness
  - Complaints, criticism, disapproval
  - Examples: "Terrible service", "So disappointed", "Worst experience"

  **Neutral**: Factual or lacking clear sentiment
  - News, announcements, questions
  - Mixed or balanced opinions
  - Examples: "The store opens at 9am", "Has anyone tried this?"

  ### Tips
  - Focus on the author's sentiment, not the topic
  - Sarcasm should be labeled based on intended meaning
  - When unsure, lower your confidence rating

# User management
automatic_assignment:
  on: true
  sampling_strategy: random
  labels_per_instance: 1
  instance_per_annotator: 100
サンプルデータの形式
data/tweets.jsonを作成します。
{"id": "t001", "text": "Just got my new laptop and I'm absolutely loving it! Best purchase of the year! #happy"}
{"id": "t002", "text": "Waited 2 hours for customer service and they still couldn't help me. Never shopping here again."}
{"id": "t003", "text": "The new coffee shop on Main Street opens tomorrow at 7am."}
{"id": "t004", "text": "This movie was okay I guess. Some good parts, some boring parts."}
{"id": "t005", "text": "Can't believe how beautiful the sunset was tonight! Nature is amazing."}
タスクの実行
アノテーションサーバーを起動します。
potato start config.yamlhttp://localhost:8000にアクセスし、ログインしてアノテーションを開始します。
サーバーが起動すると、アノテーターには次の画面が表示されます。
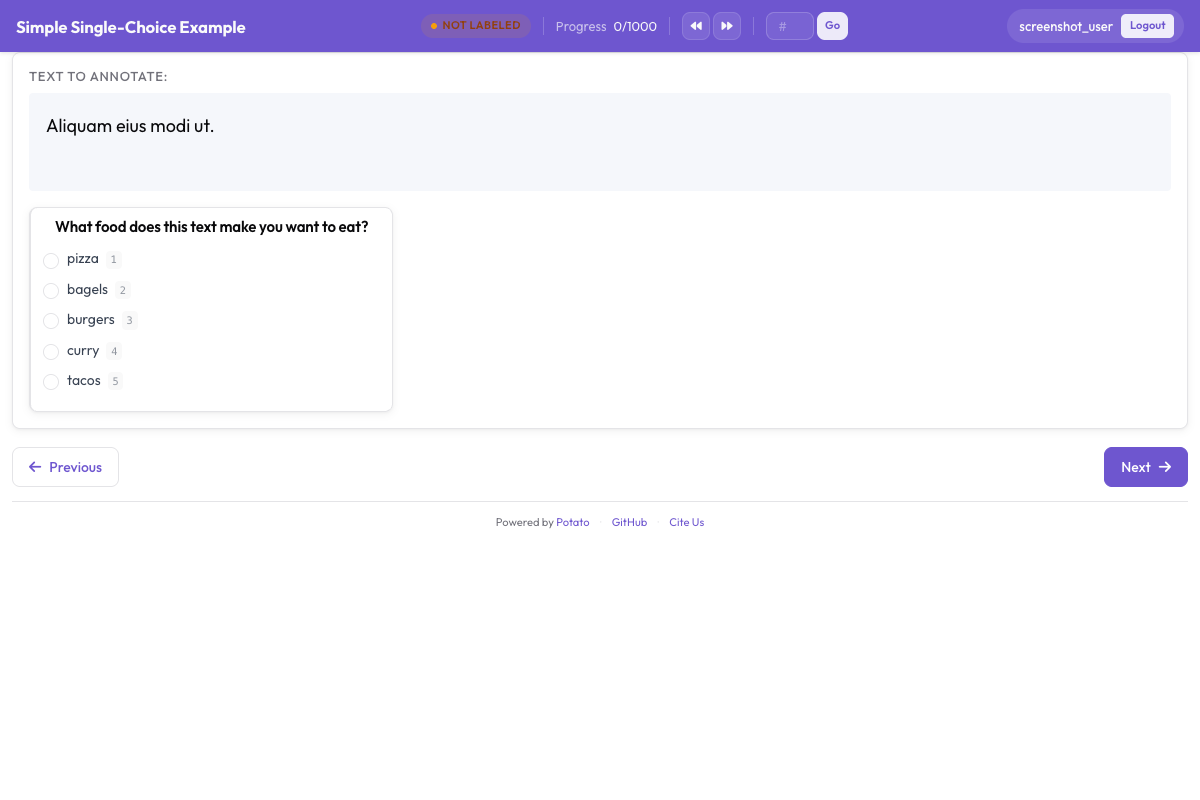 ラジオボタンのラベル、確信度スケール、任意の説明欄を表示した感情分類インターフェース
インターフェースの理解
メインのアノテーション領域
インターフェースには次のものが表示されます。
- アノテーション対象のテキスト(URL、メンション、ハッシュタグはハイライト表示)
- ツールチップ付きの感情ラジオボタン
- 確信度のLikertスケール
- 任意の説明用テキストボックス
キーボードでの作業手順
アノテーターが作業のリズムをつかむと、最も速い手順は次のようになります。
- テキストを読む
- 感情について
1、2、3のいずれかを押す - 確信度レベルをクリックする(またはマウスを使う)
Enterを押して送信する
進捗の追跡
インターフェースには次のものが表示されます。
- 現在の進捗(例:「15 / 100」)
- 推定残り時間
- セッションの統計
出力形式
各アノテーターの作業は、export_annotation_formatの設定にかかわらず<output_annotation_dir>/<user>/user_state.jsonに保存されます。この設定はそれとは別に定期的なエクスポートを追加するもので、jsonlを指定した場合、統合ファイルは<output_annotation_dir>/exports/jsonl/annotations.jsonlになり、アノテーターごと・インスタンスごとに1レコードが記録されます。
{
  "instance_id": "t001",
  "user_id": "john_doe",
  "labels": {
    "sentiment": {"Positive": "true"},
    "confidence": {"5": "true"},
    "explanation": {"text_box": "Clear expression of happiness with the purchase"}
  },
  "spans": {},
  "links": {}
}
品質管理の追加
アテンションチェック
アノテーターの注意力を確認するために、ゴールドスタンダードのアイテムを追加します。ここで使用しているradioスキーマとlikertスキーマのすべてのオプションについては、ソースドキュメントを参照してください。
attention_checks:
  enabled: true
  frequency: 10          # Every 10th item
  items_file: data/attention_checks.json
  failure_handling:
    warn_threshold: 2
block_threshold: 5アイテムは設定ファイルに直接書かずitems_fileに置き、それぞれに期待される回答を持たせます。
[
  {
    "id": "chk1",
    "text": "I am extremely happy and satisfied! This is the best!",
    "expected_answer": { "sentiment": "Positive" }
  },
  {
    "id": "chk2",
    "text": "This is absolutely terrible and I hate it completely.",
    "expected_answer": { "sentiment": "Negative" }
  }
]ゴールドスタンダードのアイテムはexpected_answerの代わりにgold_labelを使い、gold_standards.items_fileに置きます。どちらのブロックもトップレベルに置く必要があります。Potatoはattention_checksを設定のルートから読み込むため、quality_control:ブロックの中に入れると読み込まれず、エラーも報告されません。
アノテーター間一致度
研究プロジェクトでは、1つのアイテムに複数のアノテーションを付けるようにします。
automatic_assignment:
  on: true
  sampling_strategy: random
  labels_per_instance: 3  # Each item annotated by 3 people
  instance_per_annotator: 50
結果の分析
アノテーションをエクスポートして分析します。
import json
from collections import Counter

records = []
with open('annotation_output/exports/jsonl/annotations.jsonl') as f:
    for line in f:
        records.append(json.loads(line))

def chosen(record, scheme):
    """The label picked for a single-choice scheme: the key whose value is "true"."""
    for name, value in record["labels"].get(scheme, {}).items():
        if value == "true":
            return name
    return None

sentiments = Counter(chosen(r, "sentiment") for r in records)
print(f"Sentiment distribution: {dict(sentiments)}")

# A likert stores its scale position the same way, as the label name
points = [int(p) for r in records if (p := chosen(r, "confidence"))]
print(f"Average confidence: {sum(points)/len(points):.2f}")
次のステップ
- 大規模アノテーションのためにクラウドソーシングを設定する
- ラベリングを速くするためにAIによる提案を追加する
- 難しいケースを優先するためにアクティブラーニングを導入する
その他のアノテーションタイプはドキュメントをご覧ください。