音声の感情分類
インタラクティブな波形表示、再生速度コントロール、リッカートスケール、設定可能な感情ラベルセットを備えた音声感情分類タスクをPotatoで作成します。
音声感情認識(SER)は仮想アシスタント、メンタルヘルスツール、コールセンター分析で使われており、そのどれもが学習用のラベル付き音声を必要とします。このチュートリアルでは、カテゴリカルな感情、次元評価、そして複数の感情が含まれるクリップのためのアノテーションインターフェースを順に説明します。基盤となる音声オプションについては、音声アノテーションのドキュメントを参照してください。
感情アノテーションのアプローチ
音声の感情をラベル付けする一般的な方法はいくつかあります。嬉しい、悲しい、怒りといった離散カテゴリを使うことができます。感情価、覚醒度、支配性といった連続的な次元で評価することもできます。アノテーターに複数の感情を強度評価付きで同時にマークさせることもできます。また、長いクリップでは、タイムスタンプごとに異なる感情をタグ付けすることもできます。
カテゴリカル感情分類
基本セットアップ
annotation_task_name: "Speech Emotion Recognition"

data_files:
  - data/utterances.json

item_properties:
  id_key: id
  text_key: transcript  # Optional transcript

instance_display:
  fields:
    - key: audio_path
      type: audio
      label: "Utterance"
      display_options:
        controls: true
        show_waveform: true
        preload: metadata

annotation_schemes:
  - annotation_type: radio
    name: emotion
    description: "What emotion is expressed in this speech?"
    labels:
      - name: Happy
        description: "Joy, excitement, amusement"
        key_value: "h"
      - name: Sad
        description: "Sorrow, disappointment, grief"
        key_value: "s"
      - name: Angry
        description: "Frustration, irritation, rage"
        key_value: "a"
      - name: Fearful
        description: "Anxiety, worry, terror"
        key_value: "f"
      - name: Surprised
        description: "Astonishment, shock"
        key_value: "u"
      - name: Disgusted
        description: "Revulsion, distaste"
        key_value: "d"
      - name: Neutral
        description: "No clear emotion"
        key_value: "n"
    label_requirement:
      required: true
Potatoは、アノテーションラベルと並べて、再生コントロール付きのインタラクティブな波形を表示します。
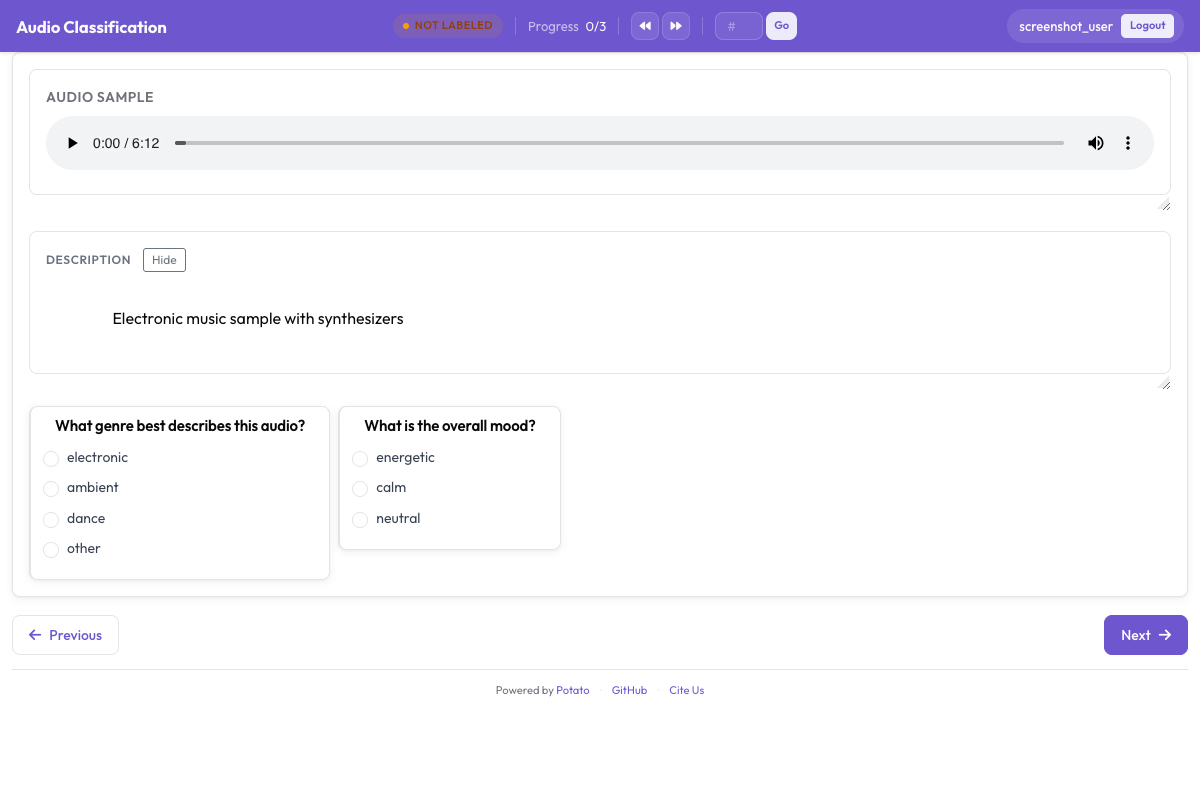 再生コントロール付きのインタラクティブな波形とカテゴリカルな感情ラベルを表示する音声アノテーションインターフェース
強度の追加
annotation_schemes:
  - annotation_type: radio
    name: emotion
    description: "What emotion does the speaker express?"
    labels: [Happy, Sad, Angry, Fearful, Surprised, Disgusted, Neutral]
    label_requirement:
      required: true

  - annotation_type: likert
    name: intensity
    description: "How intense is this emotion?"
    size: 5
    min_label: "Very weak"
    max_label: "Very strong"
次元的感情アノテーション
VAD(感情価-覚醒度-支配性)モデルは、各クリップを1つのカテゴリに押し込むのではなく、3つの連続スケールで評価します。
annotation_task_name: "Dimensional Emotion Rating"

annotation_schemes:
  # Valence: negative to positive
  - annotation_type: likert
    name: valence
    description: "Valence: How positive or negative?"
    size: 7
    min_label: "Very negative"
    max_label: "Very positive"

  # Arousal: calm to excited
  - annotation_type: likert
    name: arousal
    description: "Arousal: How calm or excited?"
    size: 7
    min_label: "Very calm"
    max_label: "Very excited"

  # Dominance: submissive to dominant
  - annotation_type: likert
    name: dominance
    description: "Dominance: How submissive or dominant?"
    size: 7
    min_label: "Very submissive"
    max_label: "Very dominant"
ビジュアルスケール(SAM)
Self-Assessment Manikinスタイル:
annotation_schemes:
  - annotation_type: likert
    min_label: "Very negative"
    max_label: "Very positive"
    name: valence
    description: "Select the figure that matches the emotional valence"
    size: 9
混合感情検出
複数の感情を含む音声の場合:
annotation_schemes:
  - annotation_type: multiselect
    name: emotions_present
    description: "Select ALL emotions you detect (can be multiple)"
    labels:
      - Happy
      - Sad
      - Angry
      - Fearful
      - Surprised
      - Disgusted
      - Contempt

  - annotation_type: radio
    name: primary_emotion
    description: "Which emotion is MOST prominent?"
    labels:
      - Happy
      - Sad
      - Angry
      - Fearful
      - Surprised
      - Disgusted
      - Contempt
      - Mixed (no dominant)
完全な感情アノテーション
annotation_task_name: "Comprehensive Speech Emotion Annotation"

data_files:
  - data/speech_samples.json

item_properties:
  id_key: id
  text_key: transcript

instance_display:
  fields:
    - key: audio_url
      type: audio
      label: "Speech sample"
      display_options:
        controls: true
        show_waveform: true
        preload: metadata
        autoplay: false

    # Show the transcript alongside the audio
    - key: transcript
      type: text
      label: "Transcript (for reference)"

annotation_schemes:
  # Primary categorical emotion
  - annotation_type: radio
    name: primary_emotion
    description: "Primary emotion expressed"
    labels:
      - name: Happiness
        color: "#FCD34D"
        key_value: "1"
      - name: Sadness
        color: "#60A5FA"
        key_value: "2"
      - name: Anger
        color: "#F87171"
        key_value: "3"
      - name: Fear
        color: "#A78BFA"
        key_value: "4"
      - name: Surprise
        color: "#34D399"
        key_value: "5"
      - name: Disgust
        color: "#FB923C"
        key_value: "6"
      - name: Neutral
        color: "#9CA3AF"
        key_value: "7"
    label_requirement:
      required: true

  # Emotional intensity
  - annotation_type: likert
    name: intensity
    description: "Emotional intensity"
    size: 5
    min_label: "Very mild"
    max_label: "Very intense"
    label_requirement:
      required: true

  # Dimensional ratings
  - annotation_type: likert
    name: valence
    description: "Valence (negative to positive)"
    size: 7
    min_label: "Negative"
    max_label: "Positive"

  - annotation_type: likert
    name: arousal
    description: "Arousal (calm to excited)"
    size: 7
    min_label: "Calm"
    max_label: "Excited"

  # Voice quality
  - annotation_type: multiselect
    name: voice_qualities
    description: "Voice characteristics (select all that apply)"
    labels:
      - Trembling voice
      - Raised pitch
      - Lowered pitch
      - Loud/shouting
      - Soft/whisper
      - Fast speech rate
      - Slow speech rate
      - Breathy
      - Tense/strained
      - Crying
      - Laughing

  # Genuineness
  - annotation_type: radio
    name: authenticity
    description: "Does the emotion seem genuine?"
    labels:
      - Clearly genuine
      - Likely genuine
      - Uncertain
      - Likely acted/fake
      - Clearly acted/fake

  # Confidence
  - annotation_type: likert
    name: confidence
    description: "How confident are you in your annotation?"
    size: 5
    min_label: "Guessing"
    max_label: "Certain"

annotation_instructions: |
  ## Emotion Annotation Guidelines

  ### Listening Instructions
  1. Listen to the entire clip before annotating
  2. You may replay as many times as needed
  3. Focus on the VOICE, not just the words

  ### Emotion Categories
  - **Happiness**: Joy, amusement, contentment
  - **Sadness**: Sorrow, disappointment, melancholy
  - **Anger**: Frustration, irritation, rage
  - **Fear**: Anxiety, nervousness, terror
  - **Surprise**: Astonishment, startle
  - **Disgust**: Revulsion, contempt
  - **Neutral**: Calm, matter-of-fact

  ### Tips
  - Consider tone, pitch, speaking rate
  - The transcript may not match the emotion
  - When unsure between two emotions, choose the stronger one
  - Use the intensity scale for unclear cases

output_annotation_dir: annotations/
export_annotation_format: jsonl
出力形式
{
  "instance_id": "utt_001",
  "user_id": "rater_01",
  "labels": {
    "primary_emotion": {"Surprise": "true"},
    "voice_qualities": {"Raised pitch": "true", "Fast speech rate": "true"},
    "authenticity": {"Clearly genuine": "true"},
    "confidence": {"4": "true"}
  },
  "spans": {},
  "links": {}
}
セグメントレベルの感情
感情が変化する長い音声の場合:
annotation_schemes:
  - annotation_type: audio_annotation
    name: emotion_segments
    description: "Mark time segments with different emotions"
    labels:
      - name: Happy
        color: "#FCD34D"
      - name: Sad
        color: "#60A5FA"
      - name: Angry
        color: "#F87171"
      - name: Neutral
        color: "#9CA3AF"
品質管理
ラベルが既知で曖昧さのないクリップを使うと、聴かずにクリックだけしているアノテーターを見つけられます。どちらのブロックも設定のトップレベルに置き、どちらもアイテムを設定内に直接書くのではなくファイルから読み込みます。
attention_checks:
  enabled: true
  frequency: 20
  items_file: data/attention_checks.json
  min_response_time: 3.0

gold_standards:
  enabled: true
  items_file: data/gold_standards.json
  mode: mixed
  frequency: 20
  accuracy:
    min_threshold: 0.7
evaluation_count: 10ゴールドアイテムは、通常のデータアイテムにgold_labelを加えた形をしているため、他のアイテムと同じように表示されます。
[
  {
    "id": "gold_001",
    "audio_path": "/audio/gold/clearly_happy.wav",
    "gold_label": { "primary_emotion": "Happiness" },
    "explanation": "Laughter and rising pitch throughout, with no ambiguity.",
    "difficulty": "easy"
  }
]注意チェックのアイテムは、gold_labelの代わりにexpected_answerを使います。音声で役に立つのはmin_response_timeです。3秒の下限を設ければ、最後まで聴き終えられたはずのないクリップにラベルを付けている人を見つけられます。
これらをquality_control:ブロックの下にネストするのはよくある間違いで、しかも何も警告されずに失敗します。Potatoはattention_checksとgold_standardsをトップレベルから読み込み、quality_controlから読むキーはgeometry_iou_toleranceだけです。そのため、ネストしたブロックは検証をエラーなしで通過し、一度も実行されません。
感情アノテーションのヒント
判断する前にクリップ全体を聴き、言葉そのものよりも、それがどのように話されているかに注意を向けてください。表現の規範は文化によって異なるため、ある文化で怒りと受け取られるものが、別の文化では強調と受け取られることがある点も念頭に置いてください。感情アノテーションは疲れる作業なので、休憩を取るよう促し、チームで意見の不一致を定期的に話し合って基準をそろえ続けてください。
次のステップ
- マルチスピーカーの感情追跡に話者ダイアライゼーションを追加
- 大規模収集にクラウドソーシングを設定
- 感情タスクのアノテーター間一致度を計算
ドキュメントは音声アノテーションをご覧ください。